---
title: "EAP Modified GRM Ability Estimation in base R"
description: "Muraki's modified graded response model (catR MGRM, mirt grsm): GRM slopes with shared category thresholds."
---
```{r options,include=FALSE}
knitr::opts_chunk$set(out.width = "60%")
```
# Background
## Acknowledgement
The functions in [`cat_eap_common.R`](https://github.com/sedzinfo/rwf/blob/main/working_examples/cat_eap_common.R) and [`cat_eap_ggrm.R`](https://github.com/sedzinfo/rwf/blob/main/working_examples/cat_eap_ggrm.R) are adapted from the source code of the **catR** package by David Magis, Gilles Raîche and Juan Ramón Barrada (Magis & Raîche, 2012; Magis & Barrada, 2017). The model parameterisations, the formulas for the response probabilities and their derivatives, the item information, maximum-information item selection and the trapezoidal EAP integration all follow catR's `Pi()`, `Ii()`, `nextItem()`, `eapEst()`, `eapSem()` and `integrate.catR()`, and much of the code keeps catR's structure line for line. The purpose of the rewrite is teaching, not replacement: every step is written out in plain base R so that it can be read, and catR remains the reference implementation that every function is checked against below. catR is free software distributed under the GNU General Public License (version 3 or later).
## Description
The companion vignette on dichotomous items builds the whole EAP pipeline, item information and next-item selection included, for items scored right/wrong under the 4PL model. This vignette does the same job for **polytomous** items — a Likert scale scored 0, 1, 2, 3, 4 — under Muraki's **modified graded response model**.
The model goes by several names, so it is worth fixing them once. Muraki (1990) introduced it as a modification of Samejima's (1969) **graded response model (GRM)**. `catR` calls it `"MGRM"`. `mirt` calls it the **graded rating scale model** (`itemtype = "grsm"`). And `cat_eap_ggrm.R` calls it the **generalized graded response model**, which is where the `_ggrm` suffix of its function names comes from. Despite that name the model is not a generalisation of the GRM but a **restriction** of it: every item keeps its own discrimination, but the spacing between its thresholds is shared by all the items that use the same rating scale. The vignette keeps the file's function names and otherwise calls the model the modified GRM, or MGRM.
[`working_examples/cat_eap_ggrm.R`](https://github.com/sedzinfo/rwf/blob/main/working_examples/cat_eap_ggrm.R) implements the model-specific part of the pipeline in six small functions, and [`working_examples/cat_eap_common.R`](https://github.com/sedzinfo/rwf/blob/main/working_examples/cat_eap_common.R) supplies the two helpers every model shares. All eight are written in base R with no runtime dependency on `catR`:
| Function | File | Purpose | `catR` equivalent it mirrors |
|---|---|---|---|
| `density_function()` | `cat_eap_common.R` | Normal density (the prior) | `stats::dnorm()` |
| `integrate_cat()` | `cat_eap_common.R` | Numerical integration (trapezoidal rule) | `catR::integrate.catR()` |
| `compute_pi_ggrm()` | `cat_eap_ggrm.R` | Category response probabilities and their first three derivatives | `catR::Pi(model="MGRM")` |
| `compute_ii_ggrm()` | `cat_eap_ggrm.R` | Item information and its first two derivatives | `catR::Ii(model="MGRM")` |
| `compute_next_item_ggrm()` | `cat_eap_ggrm.R` | Maximum Fisher information item selection, with randomesque exposure control | `catR::nextItem(model="MGRM", criterion="MFI")` |
| `compute_likelihood_ggrm()` | `cat_eap_ggrm.R` | Likelihood of a polytomous response pattern | *(internal to `catR::eapEst()`)* |
| `compute_eap_ggrm()` | `cat_eap_ggrm.R` | EAP ability estimate | `catR::eapEst(model="MGRM")` |
| `compute_eap_se_ggrm()` | `cat_eap_ggrm.R` | EAP standard error | `catR::eapSem(model="MGRM")` |
The sections below walk through the theory behind each function, validate every one of them against its `catR` counterpart, work through four properties that follow from the model's restricted form, run a small adaptive test end to end, and close with the numerical side: the integration settings and the floating-point precision of the category probabilities.
```{r source,message=FALSE,warning=FALSE}
library(ggplot2)
library(catR)
source("R/cat_eap_common.R", local = knitr::knit_global())
source("R/cat_eap_ggrm.R", local = knitr::knit_global())
# the graded response model functions, needed only for the comparison with the GRM
source("R/cat_eap_grm.R", local = knitr::knit_global())
```
---
## Theoretical Background
### Cumulative curves first, categories second
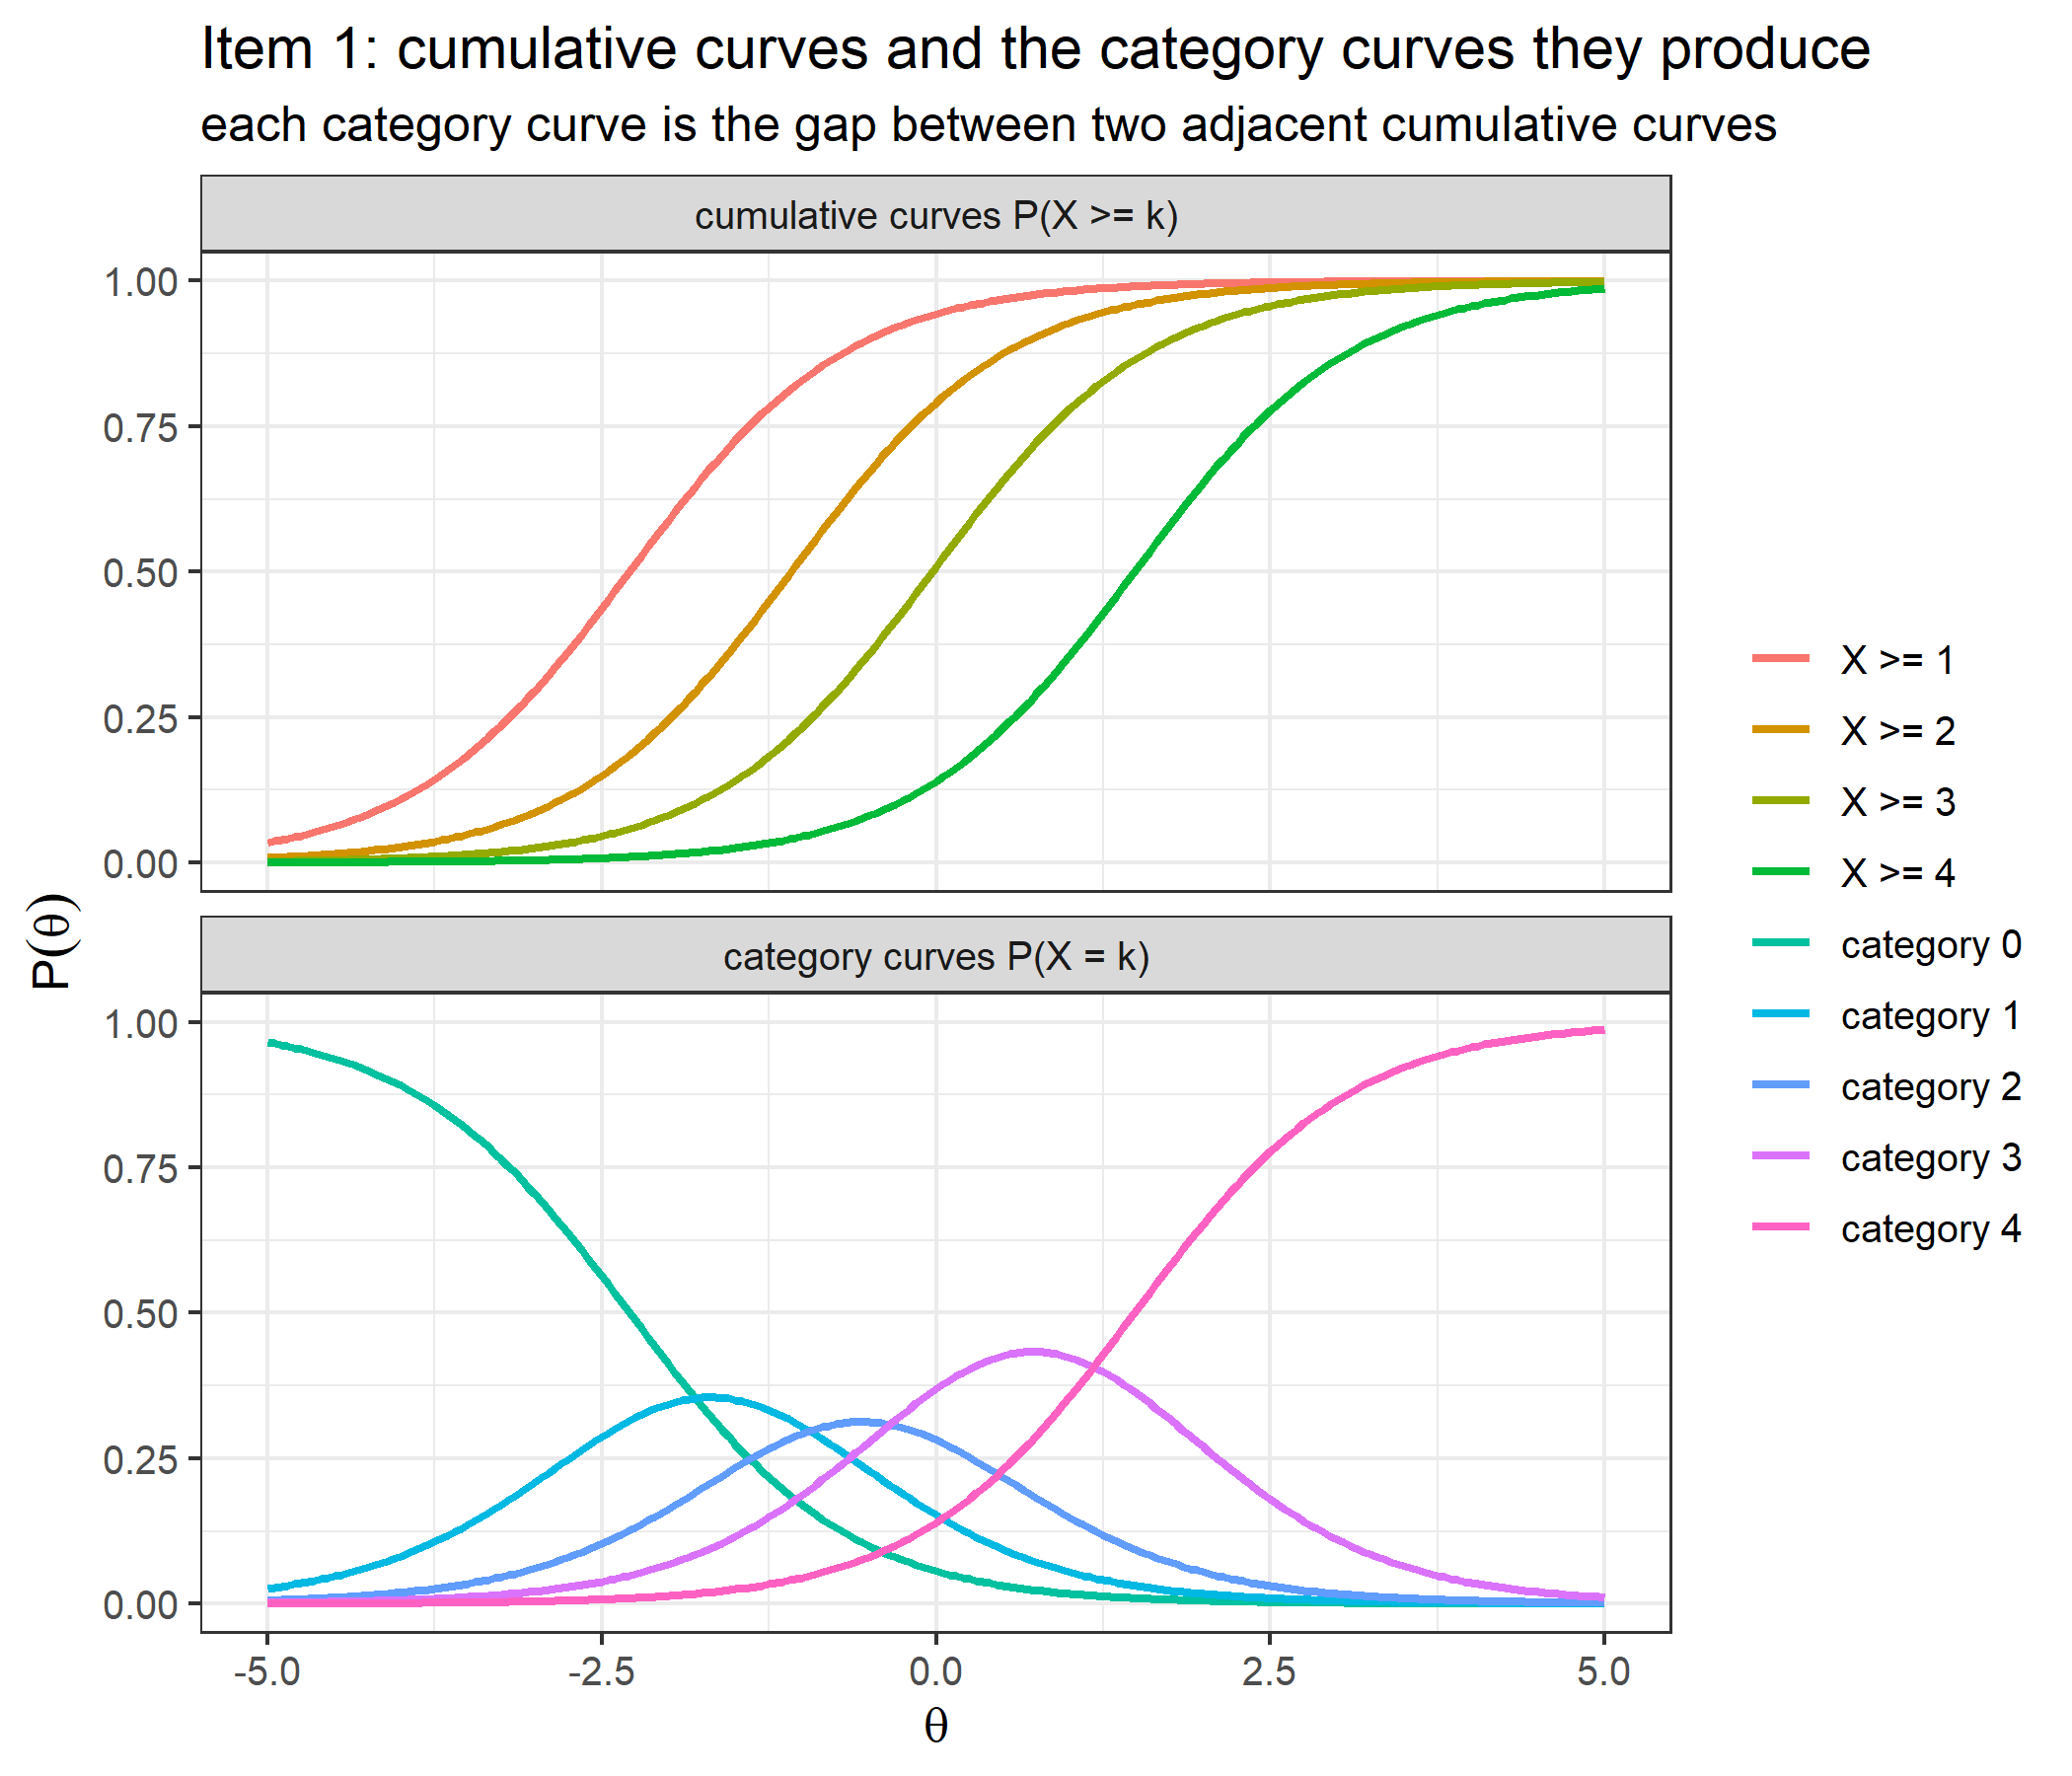
A dichotomous model needs one curve per item: the probability of a correct response. A polytomous item scored $0,1,\ldots,m$ needs $m+1$ curves — one per category — that sum to 1 at every ability level. The graded response family builds them in two steps. First, for each $k = 1,\ldots,m$ it models the **cumulative** probability of responding in category $k$ *or above* with a 2PL curve,
$$P^*_{jk}(\theta) = P(X_j \ge k \mid \theta) = \frac{\exp\big[D\alpha_j(\theta - \beta_{jk})\big]}{1 + \exp\big[D\alpha_j(\theta - \beta_{jk})\big]},$$
with the two boundary curves fixed at $P^*_{j0} = 1$ (every response is in category 0 or above) and $P^*_{j,m+1} = 0$. Second, the probability of category $k$ is the difference between two adjacent cumulative curves:
$$P_{jk}(\theta) = P(X_j = k \mid \theta) = P^*_{jk}(\theta) - P^*_{j,k+1}(\theta), \qquad k = 0,\ldots,m,$$
so the lowest category has $P_{j0} = 1 - P^*_{j1}$ and the highest $P_{jm} = P^*_{jm}$. This makes the model **cumulative**: the threshold $\beta_{jk}$ is the ability at which "category $k$ or above" becomes more likely than "below $k$". The rating scale and partial credit models are **adjacent-category** models instead: they compare each category with its neighbour and divide by a normalising total. For every difference to be a positive probability the cumulative curves must never cross or coincide, and since all $m$ curves of an item share the slope $\alpha_j$, that means the thresholds must be strictly increasing, $\beta_{j1} < \beta_{j2} < \cdots < \beta_{jm}$.
### The modified GRM: a location and shared category parameters
In Samejima's GRM every item has its own $m$ thresholds. Muraki's modification writes each threshold as an item location minus a category parameter,
$$\beta_{jk} = b_j - c_k, \qquad
P^*_{jk}(\theta) = \frac{\exp\big[D\alpha_j(\theta - b_j + c_k)\big]}{1 + \exp\big[D\alpha_j(\theta - b_j + c_k)\big]}.$$
- $\alpha_j$ — the **item discrimination**, item specific: the common slope of all $m$ cumulative curves of item $j$.
- $b_j$ — the **item location**, item specific: it moves all the thresholds of item $j$ together.
- $c_1,\ldots,c_m$ — the **category parameters**, shared by every item of a **block**, a set of items answered on the same rating scale. They fix the spacing of the thresholds, which is therefore the same for every item of the block.
- $D$ — the usual metric constant (1, or 1.702 for the normal-ogive metric).
Because $\beta_{jk} = b_j - c_k$ must increase with $k$, the category parameters must be **strictly decreasing**, $c_1 > c_2 > \cdots > c_m$.
The restriction relates the MGRM to the GRM the way the rating scale model relates to the partial credit model: one set of step parameters per block instead of one per item. Unlike the rating scale model it keeps the item discrimination. For a single block of $n$ items with $m+1$ categories the GRM has $n(m+1)$ item parameters and the MGRM $2n + m - 1$; the $-1$ is the identifiability constraint.
**Identifiability.** Only the differences $b_j - c_k$ enter the model, so adding the same constant $t$ to every $b_j$ and every $c_k$ of a block leaves every threshold, and therefore every probability, unchanged:
$$\big(b_j + t\big) - \big(c_k + t\big) = b_j - c_k = \beta_{jk}.$$
One constraint per block pins the parameters down. Muraki centres the $c_k$ of each block at zero, $\sum_{k=1}^{m} c_k = 0$, which any solution reaches with $t = -\bar c$, $\bar c = \frac{1}{m}\sum_{k=1}^{m} c_k$; `mirt` instead sets $b_j = 0$ for the first item of each block, which any solution reaches with $t$ equal to minus that item's location. Both conventions describe the same model and give the same probabilities, which a worked example below demonstrates.
### The bank layout
`cat_eap_ggrm.R` expects one row per item:
| Column | Holds |
|---|---|
| 1 | the item discrimination $\alpha_j$ |
| 2 | the item location $b_j$ |
| 3 to $m+2$ | the category parameters $c_1,\ldots,c_m$ |
A bank for items with $m+1$ categories therefore has $m+2$ columns, and the number of categories is `ncol(bank) - 1`: a five-point Likert scale scored 0 to 4 has $m = 4$ category parameters and needs a six-column bank. The category columns are identical down every row of a block, and a bank with a single block has the same $c_k$ in every row. Items answered on a different rating scale form a block of their own with their own $c_k$ — always the case for items with a different number of categories — and the shorter rows are padded with `NA` on the right. In such a bank $m$ is the number of category parameters of the widest item; item $j$ has $m_j \le m$ non-`NA` category parameters and the categories $0,\ldots,m_j$, and every formula below applies to item $j$ with $m$ replaced by $m_j$.
The columns are read by position, not by name, and each row is read on its own: nothing in the code checks that the rows of a block really share their $c_k$, and a bank in which every row had its own $c_k$ would simply be a GRM bank written in another form. `compute_pi_ggrm()`, which every other model function calls directly or through another one, begins with `bank <- rbind(bank)`, so a single item may also be passed as a plain vector `c(alpha, b, c1, ..., cm)`.
### Derivatives
Item information needs the first derivative of each category probability, and its own derivatives need the second and third. All of them come from the cumulative curves, using the logistic identity $\frac{d}{d\theta}P^* = D\alpha_j P^*(1-P^*)$ repeatedly. `compute_pi_ggrm()` evaluates them recursively, as `catR::Pi()` does:
$$\frac{dP^*_{jk}}{d\theta} = D\alpha_j P^*_{jk}\big(1-P^*_{jk}\big), \qquad
\frac{d^2P^*_{jk}}{d\theta^2} = D\alpha_j \frac{dP^*_{jk}}{d\theta}\big(1-2P^*_{jk}\big),$$
$$\frac{d^3P^*_{jk}}{d\theta^3} = D\alpha_j\left[\frac{d^2P^*_{jk}}{d\theta^2} - 2\left(\frac{dP^*_{jk}}{d\theta}\right)^2 - 2P^*_{jk}\,\frac{d^2P^*_{jk}}{d\theta^2}\right].$$
Substituting each line into the next gives the closed forms, with $W_{jk} = P^*_{jk}\big(1-P^*_{jk}\big)$:
$$\frac{dP^*_{jk}}{d\theta} = D\alpha_j W_{jk}, \qquad
\frac{d^2P^*_{jk}}{d\theta^2} = D^2\alpha_j^2 W_{jk}\big(1-2P^*_{jk}\big), \qquad
\frac{d^3P^*_{jk}}{d\theta^3} = D^3\alpha_j^3 W_{jk}\big(1-6P^*_{jk}+6P^{*2}_{jk}\big).$$
The boundary curves $P^*_{j0}=1$ and $P^*_{j,m+1}=0$ are constants with zero derivatives of every order ($W_{j0} = W_{j,m+1} = 0$), and differentiation is linear, so every derivative of a category probability is the same difference of two adjacent cumulative derivatives. Writing primes for derivatives with respect to $\theta$, for $k = 0,\ldots,m$:
$$
\begin{aligned}
P'_{jk} &= D\alpha_j\big[W_{jk} - W_{j,k+1}\big],\\
P''_{jk} &= D^2\alpha_j^2\big[W_{jk}\big(1-2P^*_{jk}\big) - W_{j,k+1}\big(1-2P^*_{j,k+1}\big)\big],\\
P'''_{jk} &= D^3\alpha_j^3\big[W_{jk}\big(1-6P^*_{jk}+6P^{*2}_{jk}\big) - W_{j,k+1}\big(1-6P^*_{j,k+1}+6P^{*2}_{j,k+1}\big)\big].
\end{aligned}
$$
`compute_pi_ggrm()` returns the four matrices `Pi`, `dPi`, `d2Pi` and `d3Pi`, holding $P_{jk}$, $P'_{jk}$, $P''_{jk}$ and $P'''_{jk}$, one row per item and one column per category: column $k+1$ (named `cat0`, `cat1`, …) holds category $k$. For an item with $m_j < m$ category parameters, the entries for the categories $k = m_j+1,\ldots,m$ are `NA` in all four matrices.
### No probability floor
The dichotomous code replaces a probability of exactly 0 or 1 by $10^{-10}$ or $1-10^{-10}$, as `catR::Pi()` does for dichotomous items. For the MGRM neither `compute_pi_ggrm()` nor `catR::Pi()` floors, clips or renormalises anything: the category probabilities are exactly the differences above. They are positive and sum to 1 when the category parameters are strictly decreasing, but far above an item's thresholds every category except the highest is the difference of two cumulative probabilities close to 1, so it loses precision and can come out as exactly 0; a worked example below measures the error. The only numerical guard is in `compute_ii_ggrm()`, which sums the information terms with `na.rm = TRUE`. That skips the `NA` entries of padded categories, and also any term that is $0/0$ because $P_{jk}$ has rounded to exactly 0 (its derivatives, computed from the same rounded cumulative probabilities, are then exactly 0 as well), so the information stays finite.
### The metric constant $D$
$D$ appears only in the product $D\alpha_j$, so for every $\theta$
$$P_{jk}\big(\theta;\,D,\,\alpha_j\big) = P_{jk}\big(\theta;\,1,\,D\alpha_j\big).$$
Setting $D = 1.702$ is therefore exactly the same model as keeping $D = 1$ and multiplying every discrimination by 1.702: it rescales the slopes and leaves the locations and category parameters alone. `catR::Pi(model = "MGRM")` applies $D$ in the same place, and every function that takes $D$ is checked against `catR` at both values below. $D$ must match the metric on which the item parameters were calibrated; parameters from `mirt` are on the $D = 1$ metric.
### Item information
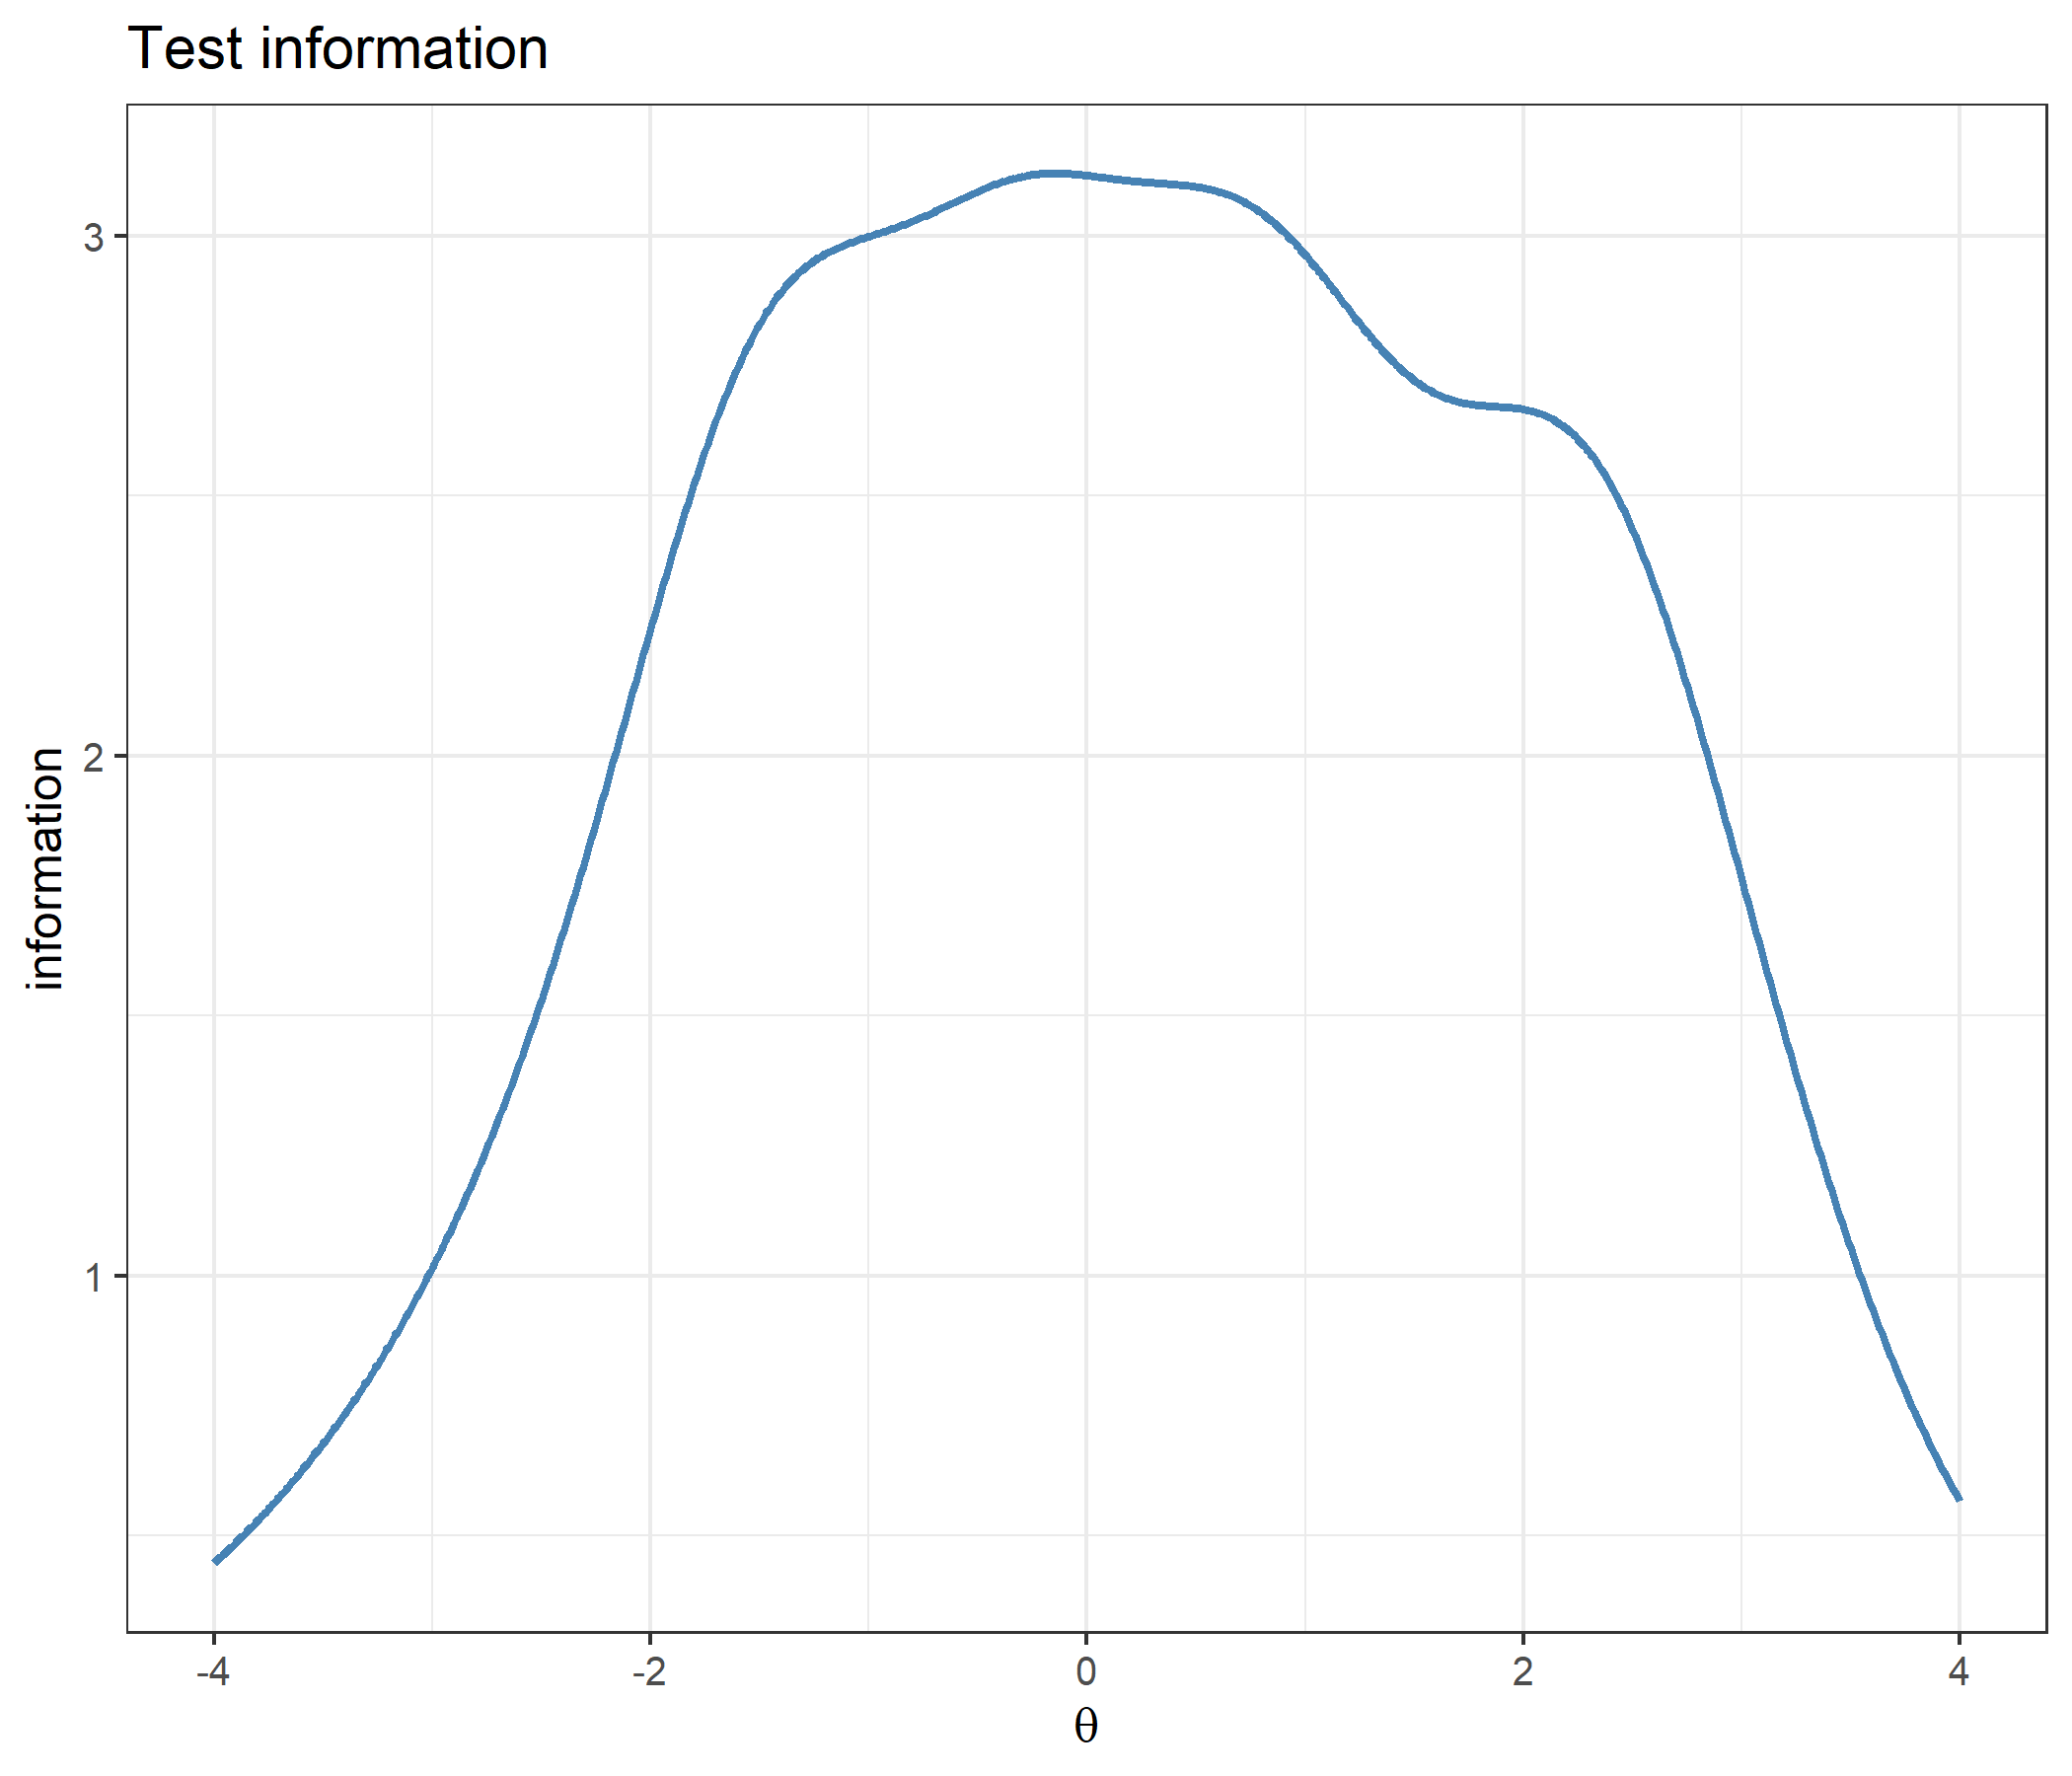
For a dichotomous item Fisher information is $I_j(\theta) = P'^2/\big(P(1-P)\big)$. The polytomous generalisation sums the same quantity over categories, and **test information** is the sum of the item informations:
$$I_j(\theta) = \sum_{k=0}^{m} \frac{\big[P'_{jk}(\theta)\big]^2}{P_{jk}(\theta)}, \qquad I(\theta) = \sum_{j=1}^{n} I_j(\theta).$$
`compute_ii_ggrm()` evaluates $I_j$ in exactly this form from the matrices of `compute_pi_ggrm()` and returns one value per item, so test information is the sum of its `Ii`. For $m = 1$ the two categories are $P$ and $1-P$ with derivatives $P'$ and $-P'$, and the sum collapses to the dichotomous formula: the item is a 2PL item with difficulty $b_j - c_1$, and $I_j = D^2\alpha_j^2\,P^*_{j1}\big(1-P^*_{j1}\big)$. `compute_ii_ggrm()` also returns the first and second derivatives of the item information with respect to $\theta$, obtained by differentiating each category term $P'^2_{jk}/P_{jk}$ and summing:
$$I'_j = \sum_{k} \left[\frac{2P'_{jk}P''_{jk}}{P_{jk}} - \frac{P'^3_{jk}}{P^2_{jk}}\right], \qquad
I''_j = \sum_{k} \left[\frac{2P''^2_{jk} + 2P'_{jk}P'''_{jk}}{P_{jk}} - \frac{5P'^2_{jk}P''_{jk}}{P^2_{jk}} + \frac{2P'^4_{jk}}{P^3_{jk}}\right].$$
Neither EAP scoring nor MFI selection uses $I'_j$ and $I''_j$; they are returned because `catR::Ii()` returns them.
Writing $\Psi$ for the logistic function and $\psi = \Psi(1-\Psi)$ for its derivative, the information of an MGRM item can be written as
$$I_j(\theta) = D^2\alpha_j^2 \sum_{k=0}^{m} \frac{\big[\psi(z_{jk}) - \psi(z_{j,k+1})\big]^2}{\Psi(z_{jk}) - \Psi(z_{j,k+1})},
\qquad z_{jk} = D\alpha_j\,(\theta - b_j + c_k),$$
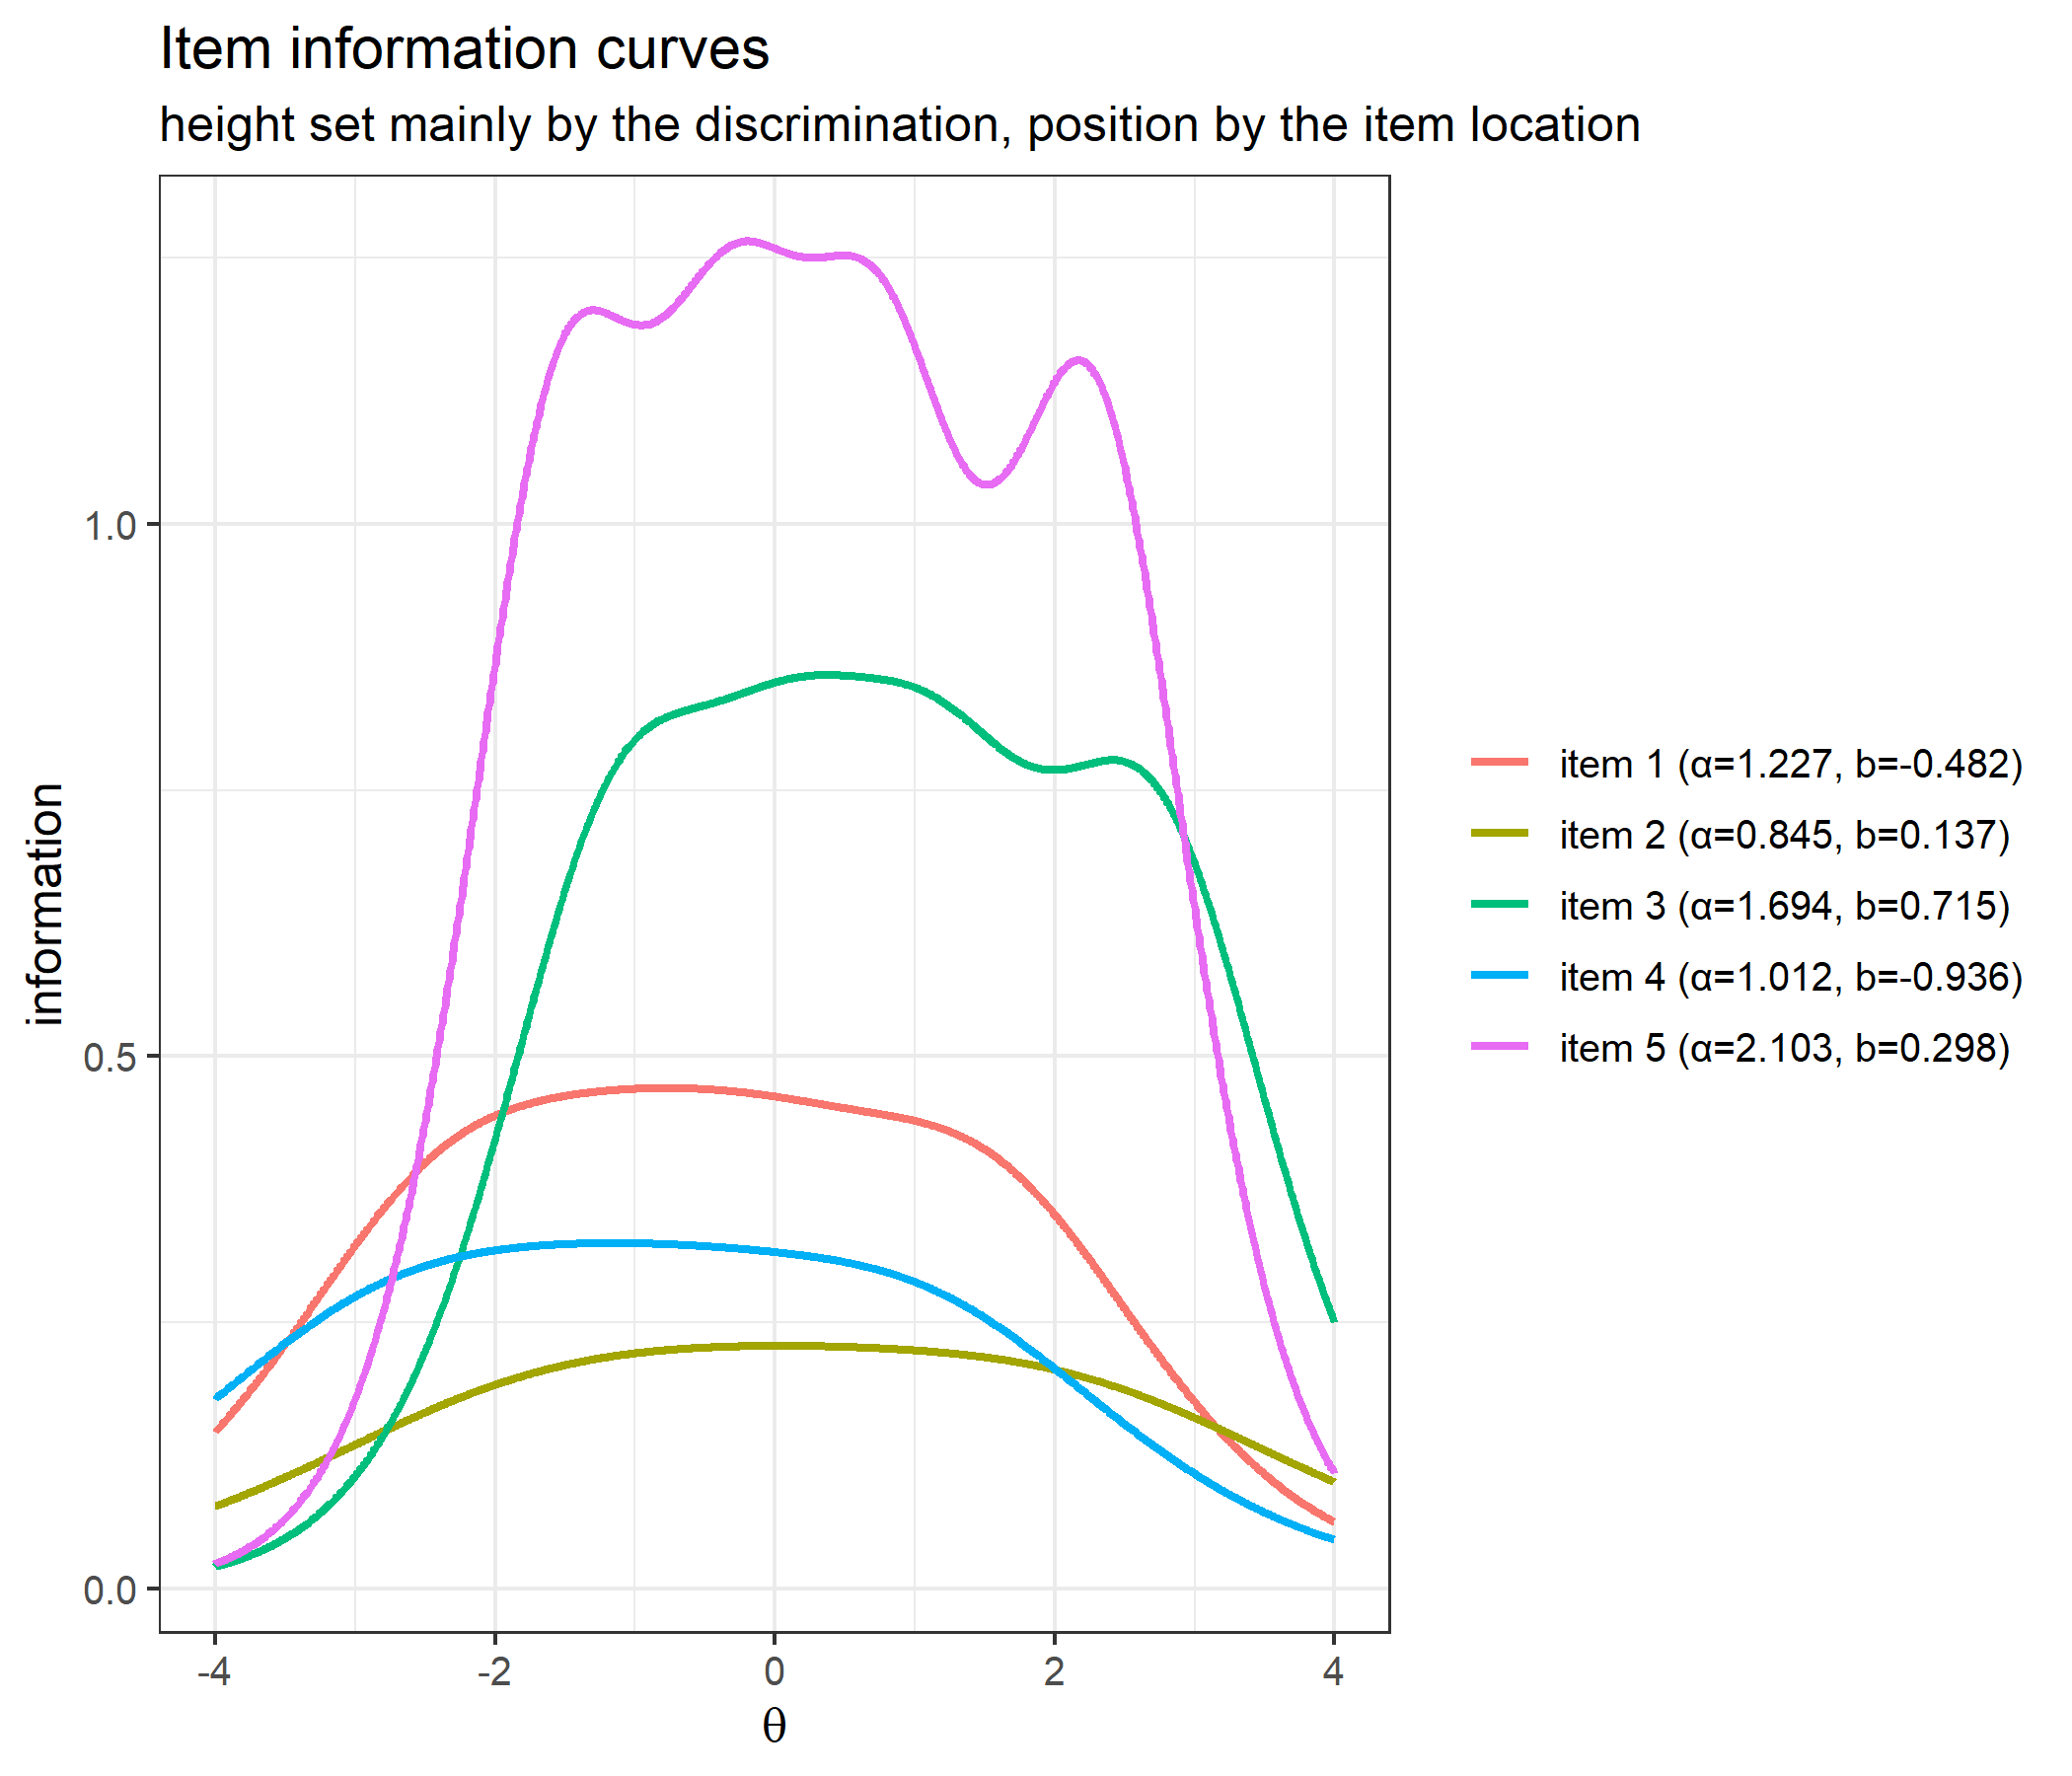
with the boundary conventions $z_{j0} = +\infty$ and $z_{j,m+1} = -\infty$, so that $\Psi(z_{j0}) = 1$, $\Psi(z_{j,m+1}) = 0$ and $\psi(z_{j0}) = \psi(z_{j,m+1}) = 0$. Two things can be read off. The ability enters only through $\theta - b_j$, and the $c_k$ are shared, so **two items of a block with the same $\alpha_j$ have the same information curve, shifted by the difference of their $b_j$**. And $\alpha_j$ enters twice: as the factor $\alpha_j^2$ in front, and inside $z_{jk}$, where it sets how far apart the thresholds are relative to the width of each logistic step. So a larger $\alpha_j$ gives a taller curve whose height grows *roughly*, not exactly, with $\alpha_j^2$, and a curve that is narrower around each threshold. Both statements are checked numerically in a worked example below.
### Next-item selection
An adaptive test picks, at each step, the unadministered item that is most informative at the current ability estimate — the **Maximum Fisher Information (MFI)** criterion. `compute_next_item_ggrm()` takes the indices of the items already administered in `out` and chooses among the rest:
$$j^{*} = \arg\max_{j\notin\texttt{out}} I_j(\hat\theta)$$
It returns the index $j^*$ as `item`, its information $I_{j^*}(\hat\theta)$ as `info`, and the indices of the items that were available as `available`; when `out` already holds every item it stops with an error.
Within a block of equal discriminations the information curves are shifted copies of one another, so the choice depends only on where $\theta$ sits relative to each $b_j$. With different discriminations the curves differ in height and shape as well, so there is no such shortcut: the information of every available item has to be computed at $\theta$, and an item with a large $\alpha_j$ whose thresholds cover the current estimate tends to win most comparisons. That is why the `randomesque` argument matters: instead of always taking the single best item it draws at random from the $k$ most informative ones, the standard way to keep a few items from being administered to almost everyone. Precisely, with
$$k = \max\Big(1,\ \min\big(\lfloor\texttt{randomesque}\rfloor,\ \text{number of available items}\big)\Big),$$
the next item is drawn with equal probabilities from the $k$ available items with the largest $I_j(\hat\theta)$, ties broken by item order as `order()` does; the default `randomesque = 1` is pure MFI and draws no random number.
Two documented differences from `catR::nextItem()` matter only for exact ties. When several items tie for the maximum, `catR` draws one of them at random while `compute_next_item_ggrm()` takes the first; and with `randomesque` above 1, `catR` also keeps every item tied with the last one kept, so it can draw from more than $k$ items. With `randomesque = 1` and no exact tie the two always choose the same item.
### Likelihood of a response pattern
Under **local independence**, the likelihood of a response pattern $\mathbf{x} = (x_1,\ldots,x_n)$, with each response coded from 0, $x_j \in \{0,\ldots,m\}$, is
$$L(\theta) = \prod_{j=1}^{n} P_{j x_j}(\theta).$$
This is the polytomous counterpart of $\prod_j P_j^{x_j}(1-P_j)^{1-x_j}$: with more than two categories there is nothing for the exponents to switch between, so the response simply indexes a column of the probability matrix. The `x[i]+1` in `compute_likelihood_ggrm()` is index bookkeeping — categories start at 0, R columns at 1 — so $P_{jx_j}$ is read from column $x_j+1$ of row $j$.
### EAP and its standard error
A **prior** $\pi(\theta)$ on ability (standard normal by default) turns the likelihood into a posterior, and EAP (Bock & Mislevy, 1982) reports its mean and standard deviation:
$$\hat\theta_{EAP} = \frac{\displaystyle\int \theta\,\pi(\theta)\,L(\theta)\,d\theta}{\displaystyle\int \pi(\theta)\,L(\theta)\,d\theta}
\qquad
SE(\hat\theta_{EAP}) = \sqrt{\frac{\displaystyle\int (\theta-\hat\theta_{EAP})^2\,\pi(\theta)\,L(\theta)\,d\theta}{\displaystyle\int \pi(\theta)\,L(\theta)\,d\theta}}$$
For a response pattern $\mathbf{x}$ with likelihood $L$, the three integrands are
$$
\begin{aligned}
g(s) &= s\,\pi(s)\,L(s),\\
h(s) &= \pi(s)\,L(s),\\
g_{SE}(s) &= (s-\hat\theta_{EAP})^2\,\pi(s)\,L(s).
\end{aligned}
$$
On the quadrature grid $X=(\theta_1,\ldots,\theta_Q)$, where $Q=\texttt{nqp}$ and $\theta_q=\texttt{lower}+(q-1)(\texttt{upper}-\texttt{lower})/(Q-1)$ (by default 33 points from $-4$ to $4$, as in `catR`), the two quantities are approximated by
$$
\hat\theta_{EAP} \approx \frac{\operatorname{Trap}(X,\,g(X))}{\operatorname{Trap}(X,\,h(X))}
\qquad
SE(\hat\theta_{EAP}) \approx \sqrt{\frac{\operatorname{Trap}(X,\,g_{SE}(X))}{\operatorname{Trap}(X,\,h(X))}},
$$
where $g(X)=(g(\theta_1),\ldots,g(\theta_Q))$, likewise for $h$ and $g_{SE}$, and `Trap` denotes the trapezoidal integration implemented by `integrate_cat()` below. `compute_eap_ggrm()` computes the first ratio. `compute_eap_se_ggrm()` computes the second with its `theta` argument in place of $\hat\theta_{EAP}$ in $g_{SE}$: passing the EAP estimate gives the posterior standard deviation, and any other value gives the larger root mean squared deviation around that value.
Maximum Likelihood has no finite maximum for a pattern in which every response sits in the lowest category, or every response in the highest: the likelihood keeps increasing towards $\theta = -\infty$ or $\theta = +\infty$. As long as the category parameters are strictly decreasing, $0 < L(\theta) \le 1$; since the normal prior has a finite mean and variance, all three integrals are then finite and the denominator positive for every response pattern, which is how the prior keeps the estimate and its standard error finite.
### Numerical integration and the prior
None of these integrals has a closed form, so the integrands are evaluated at the `nqp` quadrature points $\theta_1<\cdots<\theta_Q$ and integrated with the **trapezoidal rule**, which approximates the area between two adjacent points by a trapezoid, the width times the average of the two heights:
$$\int f(\theta)\,d\theta \approx \operatorname{Trap}(X,\,f(X)) = \sum_{q=1}^{Q-1} (\theta_{q+1}-\theta_q)\,\frac{f(\theta_q)+f(\theta_{q+1})}{2}$$
`integrate_cat()` implements exactly this sum. The prior is the normal density, which `density_function()` writes out longhand:
$$\pi(\theta) = \frac{1}{\sigma\sqrt{2\pi}}\exp\!\left(-\frac{(\theta-\mu)^2}{2\sigma^2}\right), \qquad (\mu,\sigma) = \texttt{priorPar}$$
with the default `priorPar = c(0, 1)`, the standard normal.
---
# Validation
## The item bank
The bank from the examples in `cat_eap_ggrm.R`: five items on one five-point rating scale. $\alpha_j$ and $b_j$ vary across items; the four category parameters are common to all of them.
```{r bank}
alphaj <- c(1.227, 0.845, 1.694, 1.012, 2.103)
bj     <- c(-0.482, 0.137, 0.715, -0.936, 0.298)
c1     <- rep( 1.812, 5)
c2     <- rep( 0.603, 5)
c3     <- rep(-0.452, 5)
c4     <- rep(-1.963, 5)

bank <- matrix(c(alphaj, bj, c1, c2, c3, c4), nrow = 5,
               dimnames = list(1:5, c("alphaj", "bj", "c1", "c2", "c3", "c4")))
bank
```
The bank has `r ncol(bank)` columns for `r ncol(bank) - 1` response categories. The category parameters $1.812 > 0.603 > -0.452 > -1.963$ are strictly decreasing and sum to zero, Muraki's convention.
---
## Validating each piece against `catR`
### Normal density
```{r density_check}
v <- seq(-3, 3, by = 0.1)
comparison <- data.frame(x = v, density_function = density_function(v), dnorm = dnorm(v))
head(comparison)
all.equal(comparison$density_function, comparison$dnorm)
```
```{r density_plot,dev='png'}
ggplot(comparison, aes(x = x)) +
  geom_line(aes(y = density_function, color = "density_function()"), linewidth = 1) +
  geom_point(aes(y = dnorm, color = "dnorm()"), shape = 1) +
  labs(title = "Hand-written normal density vs. dnorm()",
       x = expression(theta), y = "density", color = NULL) +
  theme_bw(base_size = 12)
```
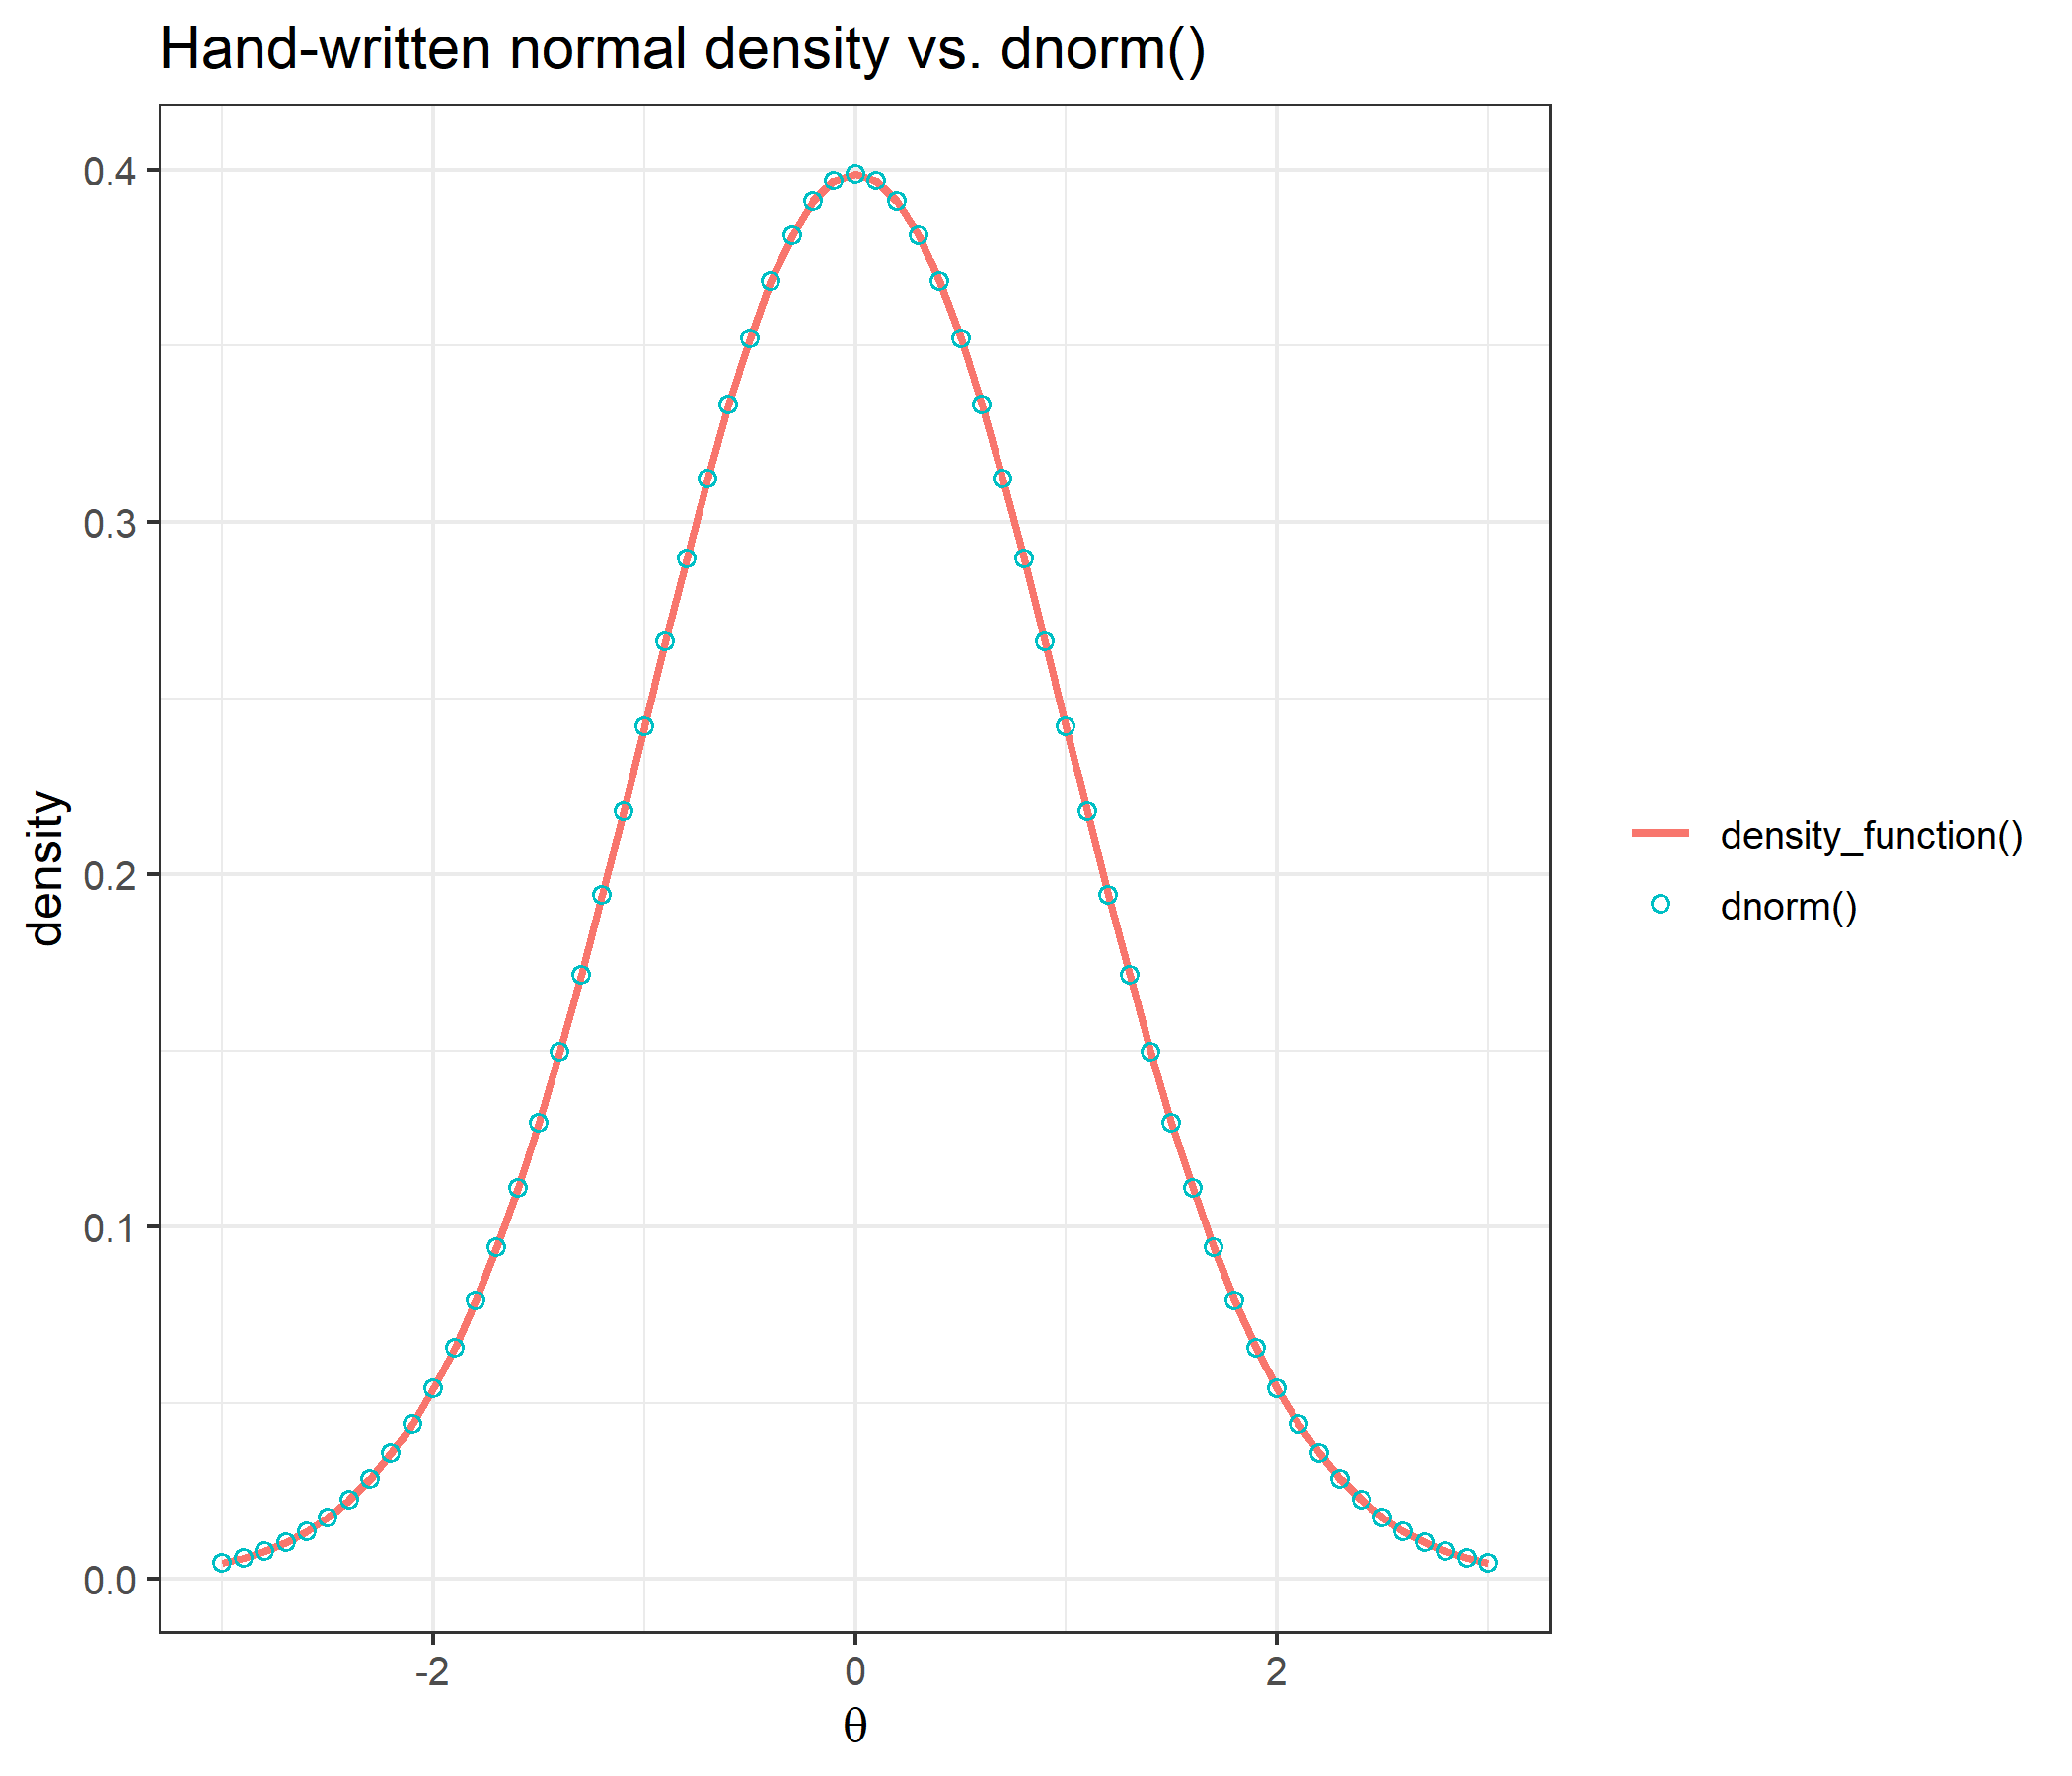
The function writes out the textbook normal density longhand. It uses `exp(1)` rather than a hard-coded `2.71828`, which is accurate to only six significant digits and, according to its documentation, shifts the EAP estimate in the seventh decimal.
### Numerical integration
```{r integration_check}
x <- seq(from = -3, to = 3, length = 33)
y <- round(exp(x), 2)
c(integrate_cat = integrate_cat(x, y), integrate.catR = catR::integrate.catR(x, y))
all.equal(integrate_cat(x, y), catR::integrate.catR(x, y))
```
Both approximate $\int_{-3}^{3} e^x\,dx$ on the same 33-point trapezoidal grid and return the same number.
### Category response probabilities and derivatives
At $\theta = 0$, the probabilities; then, at nine abilities from $-6$ to $6$ and at both metric constants, the largest absolute difference from `catR::Pi()` in each of the four returned matrices, and whether the whole returned list, dimension names included, is identical to `catR`'s:
```{r pi_check}
round(compute_pi_ggrm(theta = 0, bank)$Pi, 6)
theta_check <- c(-6, -4, -2.5, -1, 0, 0.7, 2, 4, 6)

pi_diff <- do.call(rbind, lapply(c(1, 1.702), function(D) {
  do.call(rbind, lapply(theta_check, function(th) {
    mine   <- compute_pi_ggrm(theta = th, bank, D = D)
    theirs <- catR::Pi(th = th, bank, model = "MGRM", D = D)
    data.frame(D = D, theta = th,
               Pi   = max(abs(mine$Pi   - theirs$Pi)),
               dPi  = max(abs(mine$dPi  - theirs$dPi)),
               d2Pi = max(abs(mine$d2Pi - theirs$d2Pi)),
               d3Pi = max(abs(mine$d3Pi - theirs$d3Pi)),
               identical = identical(mine, theirs))
  }))
}))
pi_diff
```
The largest difference over all `r nrow(pi_diff)` comparisons and all four matrices is `r max(pi_diff[, c("Pi", "dPi", "d2Pi", "d3Pi")])`, and `r sum(pi_diff$identical)` of the `r nrow(pi_diff)` returned lists are identical to `catR`'s: the arithmetic is the same as `catR`'s, operation for operation.
Items answered on a different rating scale form a block with its own category parameters, and a scale with fewer categories leaves its rows padded with `NA`. Here three four-category items (scored 0 to 3, so three category parameters, centred at zero) are added to the bank and compared with `catR` on the same grid:
```{r pi_check_two_blocks}
bank_two_blocks <- rbind(bank,
                         "6" = c(1.400, -0.300, 1.2, 0, -1.2, NA),
                         "7" = c(0.900,  0.500, 1.2, 0, -1.2, NA),
                         "8" = c(1.100,  0.100, 1.2, 0, -1.2, NA))
P_two_blocks <- compute_pi_ggrm(theta = 0, bank_two_blocks)$Pi
round(P_two_blocks, 6)
rowSums(P_two_blocks, na.rm = TRUE)
all(sapply(c(1, 1.702), function(D) sapply(theta_check, function(th)
  identical(compute_pi_ggrm(theta = th, bank_two_blocks, D = D),
            catR::Pi(th = th, bank_two_blocks, model = "MGRM", D = D)))))
```
Items 6 to 8 have `NA` for `cat4` — the category does not exist — and the probabilities of every item still sum to 1. All four matrices, `NA`s included, are identical to `catR`'s at every point of the grid; the EAP check below scores a pattern on this bank as well.
```{r pi_plot,dev='png'}
theta_grid <- seq(-5, 5, by = 0.05)
curves <- t(sapply(theta_grid, function(th) compute_pi_ggrm(theta = th, bank)$Pi[1, ]))
cumulative <- t(apply(curves, 1, function(p) rev(cumsum(rev(p)))[-1]))   # P(X >= k), k = 1..4

df_category <- data.frame(theta = theta_grid, curves)
names(df_category)[-1] <- paste0("category ", 0:4)
df_cumulative <- data.frame(theta = theta_grid, cumulative)
names(df_cumulative)[-1] <- paste0("X >= ", 1:4)

df_long <- rbind(
  transform(reshape2::melt(df_cumulative, id.vars = "theta",
                           variable.name = "curve", value.name = "P"),
            panel = "cumulative curves P(X >= k)"),
  transform(reshape2::melt(df_category, id.vars = "theta",
                           variable.name = "curve", value.name = "P"),
            panel = "category curves P(X = k)"))
df_long$panel <- factor(df_long$panel, levels = unique(df_long$panel))

ggplot(df_long, aes(x = theta, y = P, color = curve)) +
  geom_line(linewidth = 1) +
  facet_wrap(~ panel, ncol = 1) +
  labs(title = "Item 1: cumulative curves and the category curves they produce",
       subtitle = "each category curve is the gap between two adjacent cumulative curves",
       x = expression(theta), y = expression(P(theta)), color = NULL) +
  theme_bw(base_size = 12)
```
The top panel shows four parallel 2PL curves, one per threshold of item 1, all with the slope $\alpha_1$; the bottom panel shows the gaps between them.
### Item information
At $\theta = 0$, the information of each item next to `catR::Ii()`; then every element — `Ii`, `dIi` and `d2Ii` — on the same grid of abilities and metric constants, as the largest absolute difference in each:
```{r ii_check}
data.frame(mine = compute_ii_ggrm(theta = 0, bank)$Ii,
           catR = catR::Ii(th = 0, bank, model = "MGRM")$Ii)
ii_diff <- do.call(rbind, lapply(c(1, 1.702), function(D) {
  do.call(rbind, lapply(theta_check, function(th) {
    mine   <- compute_ii_ggrm(theta = th, bank, D = D)
    theirs <- catR::Ii(th = th, bank, model = "MGRM", D = D)
    data.frame(D = D, theta = th,
               Ii   = max(abs(mine$Ii   - theirs$Ii)),
               dIi  = max(abs(mine$dIi  - theirs$dIi)),
               d2Ii = max(abs(mine$d2Ii - theirs$d2Ii)))
  }))
}))
ii_diff
max(ii_diff[, c("Ii", "dIi", "d2Ii")])
```
```{r ii_plot,dev='png'}
info_grid <- seq(-4, 4, by = 0.01)
info <- t(sapply(info_grid, function(th) compute_ii_ggrm(th, bank)$Ii))
df_info <- data.frame(theta = info_grid, info)
names(df_info)[-1] <- paste0("item ", 1:5, " (α=", alphaj, ", b=", bj, ")")
df_info_long <- reshape2::melt(df_info, id.vars = "theta",
                               variable.name = "item", value.name = "information")

ggplot(df_info_long, aes(x = theta, y = information, color = item)) +
  geom_line(linewidth = 1) +
  labs(title = "Item information curves",
       subtitle = "height set mainly by the discrimination, position by the item location",
       x = expression(theta), y = "information", color = NULL) +
  theme_bw(base_size = 12)
```
```{r test_info_plot,dev='png'}
df_test <- data.frame(theta = info_grid, information = rowSums(info))

ggplot(df_test, aes(x = theta, y = information)) +
  geom_line(linewidth = 1, color = "steelblue") +
  labs(title = "Test information", x = expression(theta), y = "information") +
  theme_bw(base_size = 12)
```
The curves differ in height and in shape, not only in position; the worked example on the information curves below separates the part of that caused by the discriminations from the part caused by the shared category parameters.
### Next-item selection
At $\theta = 0$, and then across a grid of abilities at both metric constants:
```{r next_item_check}
mine   <- compute_next_item_ggrm(theta = 0, bank)
theirs <- catR::nextItem(bank, model = "MGRM", theta = 0, criterion = "MFI")
c(mine_item = mine$item, catR_item = theirs$item,
  mine_info = mine$info, catR_info = theirs$info)
next_diff <- do.call(rbind, lapply(c(1, 1.702), function(D) {
  do.call(rbind, lapply(seq(-3, 3, by = 0.5), function(th) {
    mine   <- compute_next_item_ggrm(theta = th, bank, D = D)
    theirs <- catR::nextItem(bank, model = "MGRM", theta = th, criterion = "MFI", D = D)
    data.frame(D = D, theta = th, mine = mine$item, catR = theirs$item,
               info_difference = abs(mine$info - theirs$info))
  }))
}))
c(agreements = sum(next_diff$mine == next_diff$catR), comparisons = nrow(next_diff),
  max_info_difference = max(next_diff$info_difference))
```
With items already administered excluded via `out`:
```{r next_item_out}
out_sets <- list(5, c(5, 3), c(5, 3, 1), c(5, 3, 1, 4))
do.call(rbind, lapply(out_sets, function(o) data.frame(
  out  = paste(o, collapse = ", "),
  mine = compute_next_item_ggrm(theta = 0.5, bank, out = o)$item,
  catR = catR::nextItem(bank, model = "MGRM", theta = 0.5, out = o, criterion = "MFI")$item)))
```
The documented differences are in the handling of exact ties, and the first one is easy to show. A bank in which the first two rows are the same item makes the most informative item tied by construction. `catR::nextItem()` re-seeds the random-number generator with `set.seed(NULL)` before it returns, so its draws are made reproducible here with its own `random.seed` argument, one seed per call:
```{r next_item_ties}
bank_tied_items <- bank[c(1, 1, 2), ]
table(mine = replicate(200, compute_next_item_ggrm(theta = -0.8, bank_tied_items)$item))
table(catR = sapply(1:200, function(s)
  catR::nextItem(bank_tied_items, model = "MGRM", theta = -0.8, criterion = "MFI",
                 random.seed = s)$item))
```
`compute_next_item_ggrm()` takes the first of the tied items every time; `catR` draws between them at random. With continuous item parameters exact ties are rare, which is why the grid comparison above agrees everywhere.
### Likelihood
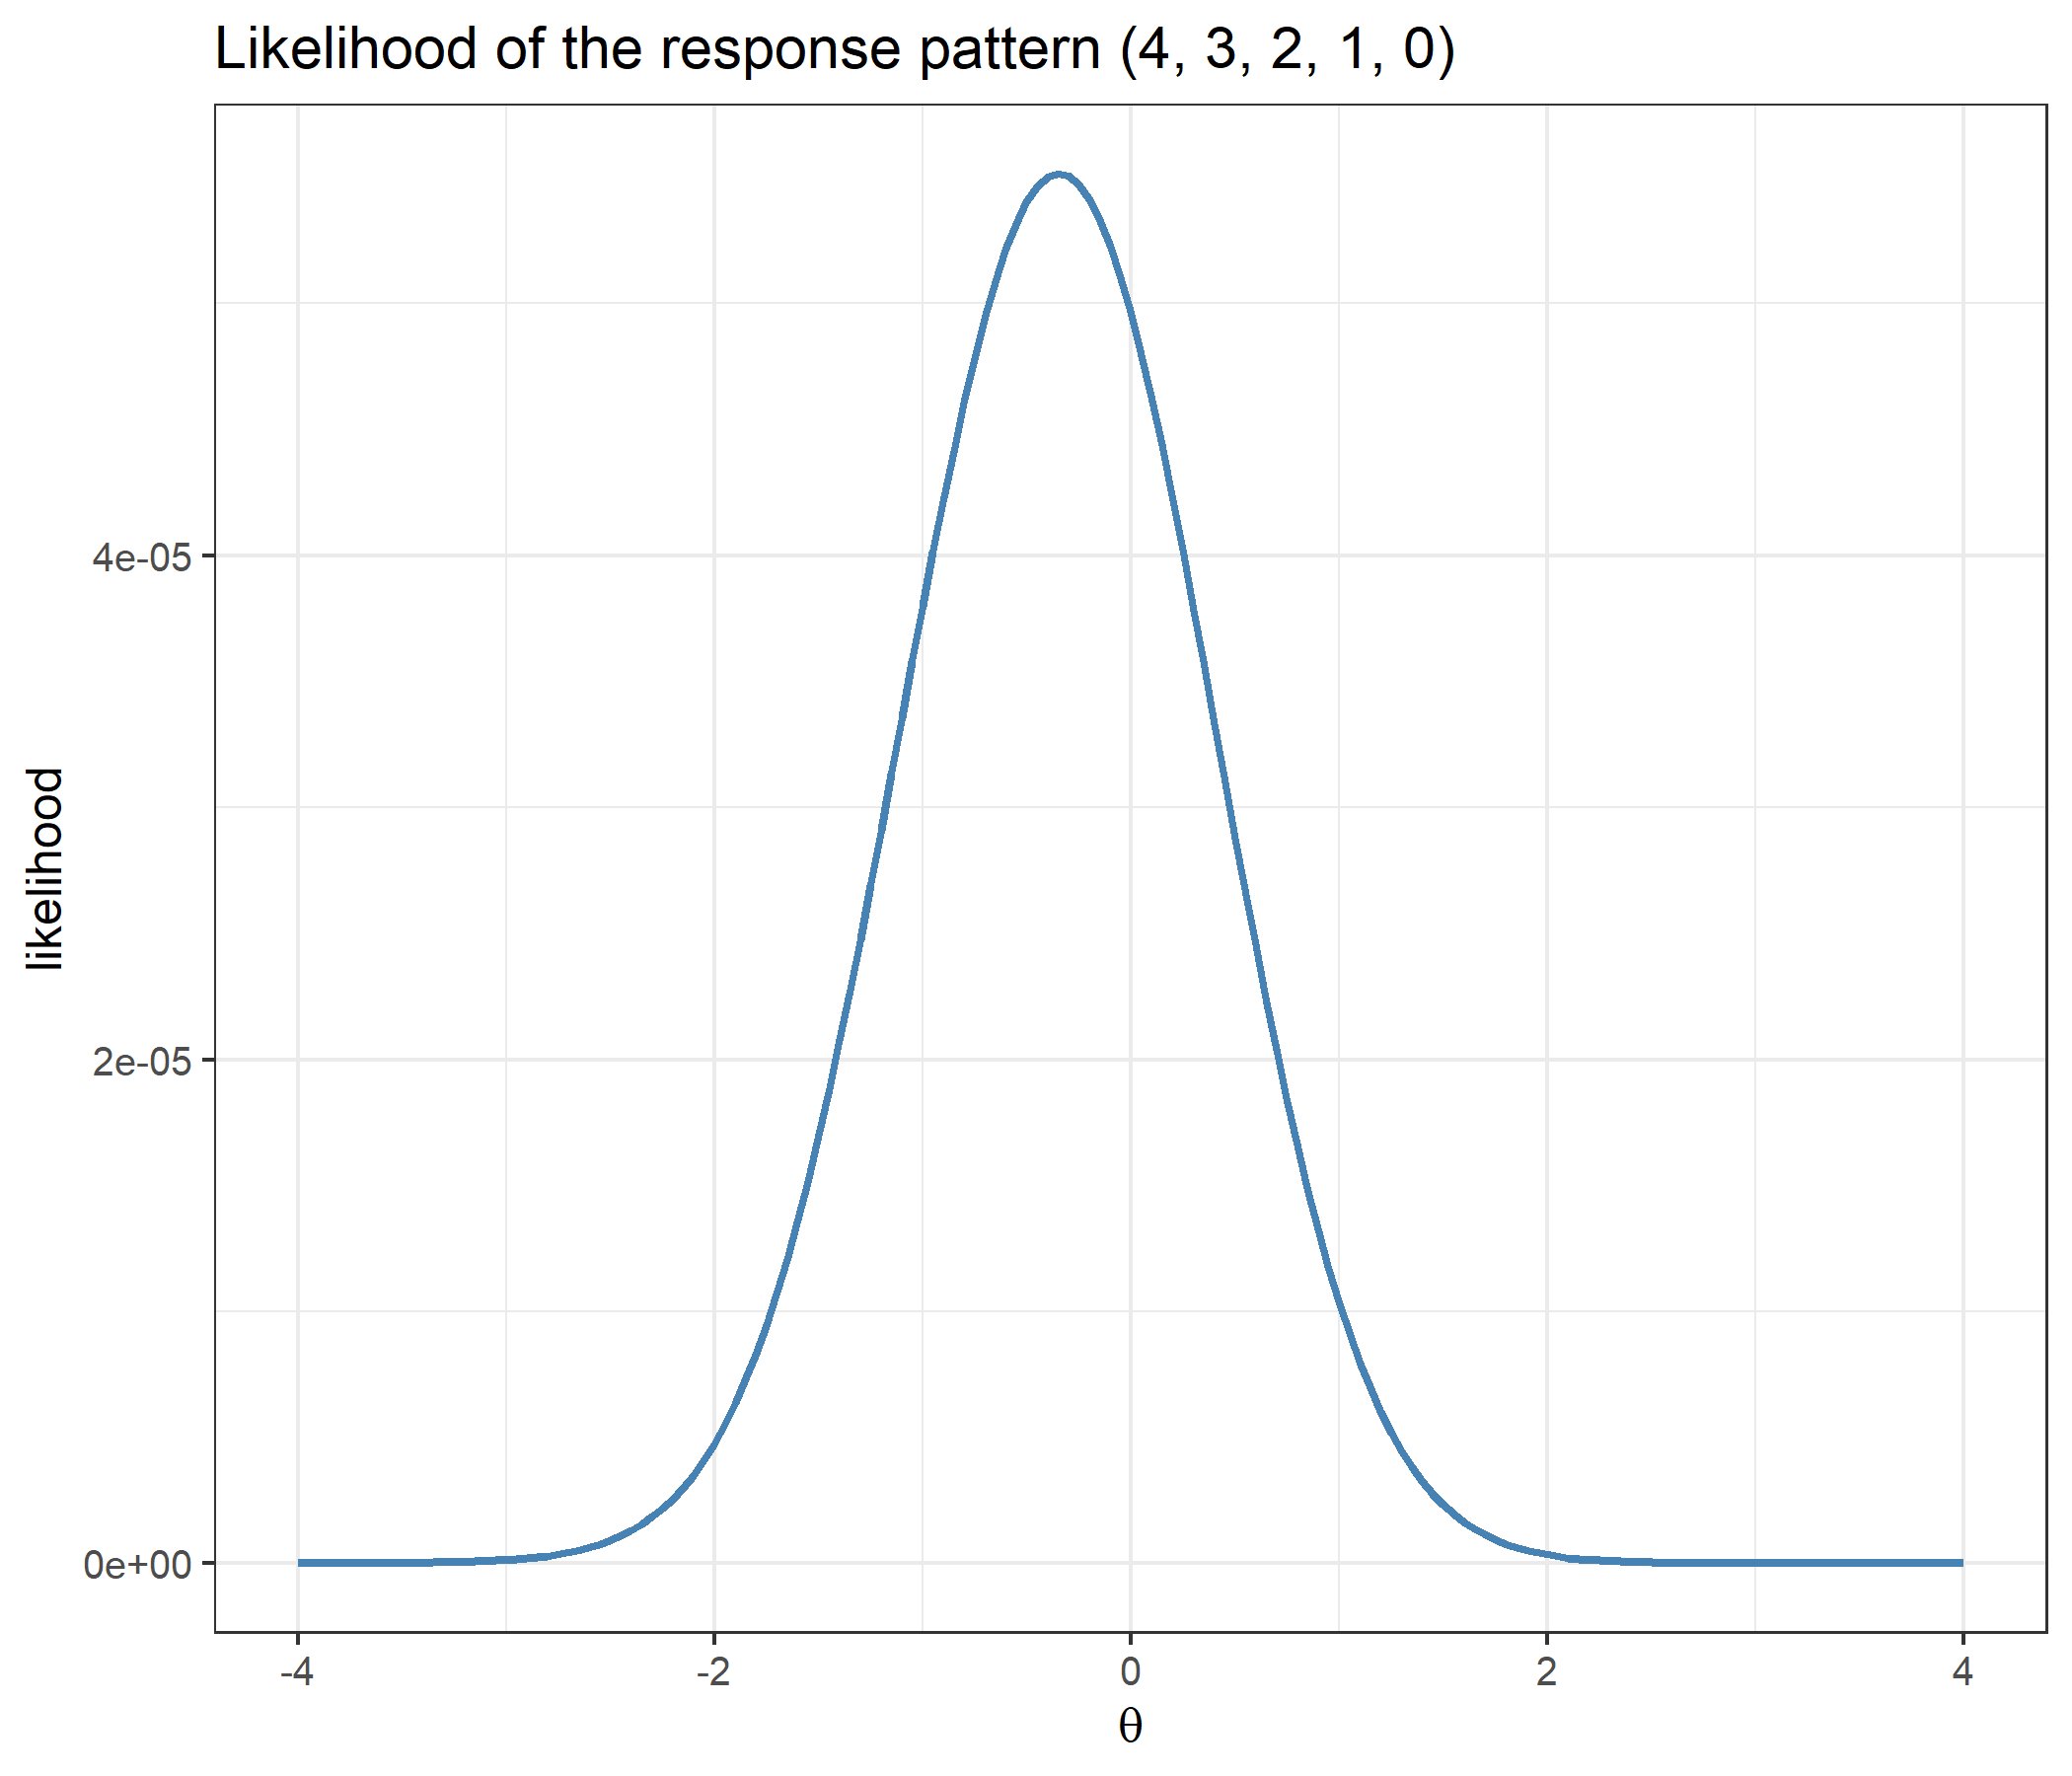
`catR` has no exported likelihood function to compare against, so the check reconstructs the same product from `catR`'s own probability matrix, $\prod_j P_{jx_j}$ with $P_{jx_j}$ taken from column $x_j + 1$, at several abilities and both metric constants:
```{r likelihood_check}
response <- c(4, 3, 2, 1, 0)

lik_check <- do.call(rbind, lapply(c(1, 1.702), function(D) {
  do.call(rbind, lapply(c(-4, -1, 0.3, 2, 4), function(th) {
    P_catR <- catR::Pi(th = th, bank, model = "MGRM", D = D)$Pi
    mine   <- compute_likelihood_ggrm(theta = th, bank = bank, x = response, D = D)
    manual <- prod(P_catR[cbind(1:5, response + 1)])
    data.frame(D = D, theta = th, compute_likelihood_ggrm = mine, from_catR_Pi = manual,
               relative_difference = abs(mine - manual) / manual)
  }))
}))
lik_check
```
```{r likelihood_plot,dev='png'}
lik_grid <- seq(-4, 4, by = 0.05)
df_lik <- data.frame(theta = lik_grid,
                     likelihood = sapply(lik_grid, function(th)
                       compute_likelihood_ggrm(th, bank, response)))

ggplot(df_lik, aes(x = theta, y = likelihood)) +
  geom_line(linewidth = 1, color = "steelblue") +
  labs(title = "Likelihood of the response pattern (4, 3, 2, 1, 0)",
       x = expression(theta), y = "likelihood") +
  theme_bw(base_size = 12)
```
### EAP ability estimate and standard error
Eight patterns on the five-item bank — the five uniform ones, including the two extremes, and three mixed ones — and one on the two-block bank with its `NA` padding, where items 6 to 8 can only be scored 0 to 3, at both metric constants:
```{r eap_check}
patterns <- list(c(0, 0, 0, 0, 0), c(1, 1, 1, 1, 1), c(2, 2, 2, 2, 2),
                 c(3, 3, 3, 3, 3), c(4, 4, 4, 4, 4), c(4, 3, 2, 1, 0),
                 c(0, 1, 2, 3, 4), c(0, 4, 0, 4, 0),
                 c(4, 3, 2, 1, 0, 3, 0, 2))   # eight responses: the two-block bank

validation <- do.call(rbind, lapply(c(1, 1.702), function(D) {
  do.call(rbind, lapply(patterns, function(x) {
    b <- if (length(x) == nrow(bank)) bank else bank_two_blocks
    th_mine <- compute_eap_ggrm(b, x, D = D)
    th_catR <- catR::eapEst(b, x, model = "MGRM", D = D)
    data.frame(D = D,
               pattern  = paste(x, collapse = " "),
               eap_mine = th_mine,
               eap_catR = th_catR,
               se_mine  = compute_eap_se_ggrm(th_mine, b, x, D = D),
               se_catR  = catR::eapSem(th_mine, b, x, model = "MGRM", D = D))
  }))
}))
validation
c(max_eap_difference = max(abs(validation$eap_mine - validation$eap_catR)),
  max_se_difference  = max(abs(validation$se_mine  - validation$se_catR)))
```
Both the point estimate and the standard error reproduce `catR` to machine precision for every pattern, at both metric constants — the largest differences are `r format(signif(max(abs(validation$eap_mine - validation$eap_catR)), 2))` for the estimate and `r format(signif(max(abs(validation$se_mine - validation$se_catR)), 2))` for the standard error — including the all-lowest and all-highest patterns, where Maximum Likelihood would have failed outright, and the `NA`-padded items of the two-block bank.
---
# Examples
## Worked example: a restricted graded response model
Computing the thresholds $\beta_{jk} = b_j - c_k$ turns an MGRM bank into an ordinary GRM bank, laid out the way `cat_eap_grm.R` expects (discrimination, then the $m$ thresholds), with the discriminations unchanged:
$$\big(\alpha_j,\ b_j,\ c_1,\ldots,c_m\big) \;\longmapsto\; \big(\alpha_j,\ b_j - c_1,\ \ldots,\ b_j - c_m\big).$$
The thresholds of the bank, and the gaps between consecutive thresholds:
```{r as_grm}
bank_as_grm <- cbind(bank[, "alphaj"], bank[, "bj"] - bank[, c("c1", "c2", "c3", "c4")])
colnames(bank_as_grm) <- c("alphaj", "betaj1", "betaj2", "betaj3", "betaj4")
bank_as_grm
round(t(apply(bank_as_grm[, -1], 1, diff)), 12)
```
Every item has its own thresholds, but the gaps between them are the same in every row — `r paste(round(-diff(bank[1, 3:6]), 3), collapse = ", ")`, the differences $c_k - c_{k+1}$. That is the restriction made concrete: each item's set of thresholds is the same ladder, slid along the ability axis by $b_j$. Passed to `compute_pi_grm()`, the converted bank gives the same output as the original bank passed to `compute_pi_ggrm()`:
```{r as_grm_identical}
grm_grid <- seq(-4, 4, by = 0.25)
same_output <- sapply(grm_grid, function(th)
  identical(compute_pi_ggrm(th, bank), compute_pi_grm(th, bank_as_grm)))
c(identical = sum(same_output), grid_points = length(grm_grid))
```
The two functions return **identical** results — all four matrices, bit for bit — at every one of the `r length(grm_grid)` grid points. That is not a coincidence of rounding: `compute_pi_ggrm()` forms $b_j - c_k$ as its first step and then runs exactly the code of `compute_pi_grm()`. Scoring agrees as well, both here and in `catR`:
```{r as_grm_eap}
x <- c(4, 3, 2, 1, 0)
c(compute_eap_ggrm = compute_eap_ggrm(bank, x),
  compute_eap_grm  = compute_eap_grm(bank_as_grm, x),
  catR_MGRM        = catR::eapEst(bank, x, model = "MGRM"),
  catR_GRM         = catR::eapEst(bank_as_grm, x, model = "GRM"))
```
The conversion only runs one way. A GRM bank can be written as an MGRM bank only if the gaps between consecutive thresholds are the same for every item of a block, $\beta_{j,k+1} - \beta_{jk} = c_k - c_{k+1}$ for every item $j$ of the block. The bank from the examples of `cat_eap_grm.R` shows the usual situation:
```{r grm_spacing}
grm_example <- matrix(c(1.227, 0.845, 1.694, 1.012, 2.103,
                        -2.183, -1.542, -1.021, -2.460, -0.812,
                        -0.874, -0.415, -0.231, -1.105, 0.094,
                        0.316, 0.783, 0.652, 0.047, 0.881,
                        1.592, 2.064, 1.438, 1.271, 1.736), nrow = 5,
                      dimnames = list(1:5, c("alphaj", "betaj1", "betaj2", "betaj3", "betaj4")))
t(apply(grm_example[, 2:5], 1, diff))
```
Every item has its own gaps, so no choice of $b_j$ and shared $c_k$ can reproduce these thresholds. The MGRM spends `r 2 * nrow(bank) + (ncol(bank) - 2) - 1` item parameters on a five-item, five-category block where the GRM spends `r nrow(bank) * (ncol(bank) - 1)`, and the price is exactly this assumption: the rating scale is used with the same spacing on every item.
### What the restriction does not buy: a sufficient raw score
Under the rating scale model the raw score is a sufficient statistic, so patterns with the same total get the same estimate. The MGRM shares the rating scale model's idea of a common set of step parameters, but not that property. Five patterns that all sum to 10, scored with the bank as given and with a copy in which every discrimination is set to the same value:
```{r not_sufficient}
same_total <- list(c(2, 2, 2, 2, 2), c(4, 3, 2, 1, 0), c(0, 1, 2, 3, 4),
                   c(4, 4, 2, 0, 0), c(0, 0, 2, 4, 4))

bank_equal_alpha <- bank
bank_equal_alpha[, "alphaj"] <- 1.227

sufficiency <- data.frame(
  pattern     = sapply(same_total, paste, collapse = " "),
  raw_score   = sapply(same_total, sum),
  theta_EAP   = sapply(same_total, function(x) compute_eap_ggrm(bank, x)),
  theta_EAP_equal_alpha = sapply(same_total, function(x) compute_eap_ggrm(bank_equal_alpha, x)))
sufficiency
```
With the discriminations as given the five estimates range from `r round(min(sufficiency$theta_EAP), 3)` to `r round(max(sufficiency$theta_EAP), 3)`: which items the high responses fall on matters, through both their discriminations and their locations. Making the discriminations equal narrows the range to `r round(min(sufficiency$theta_EAP_equal_alpha), 3)` to `r round(max(sufficiency$theta_EAP_equal_alpha), 3)` but does not close it. The reason is the cumulative form: a category probability is a difference of two logistic curves, not an exponential of a linear function of $\theta$, so the likelihood does not depend on the pattern only through its total, whatever the discriminations are.
---
## Worked example: shared category parameters and the information curves
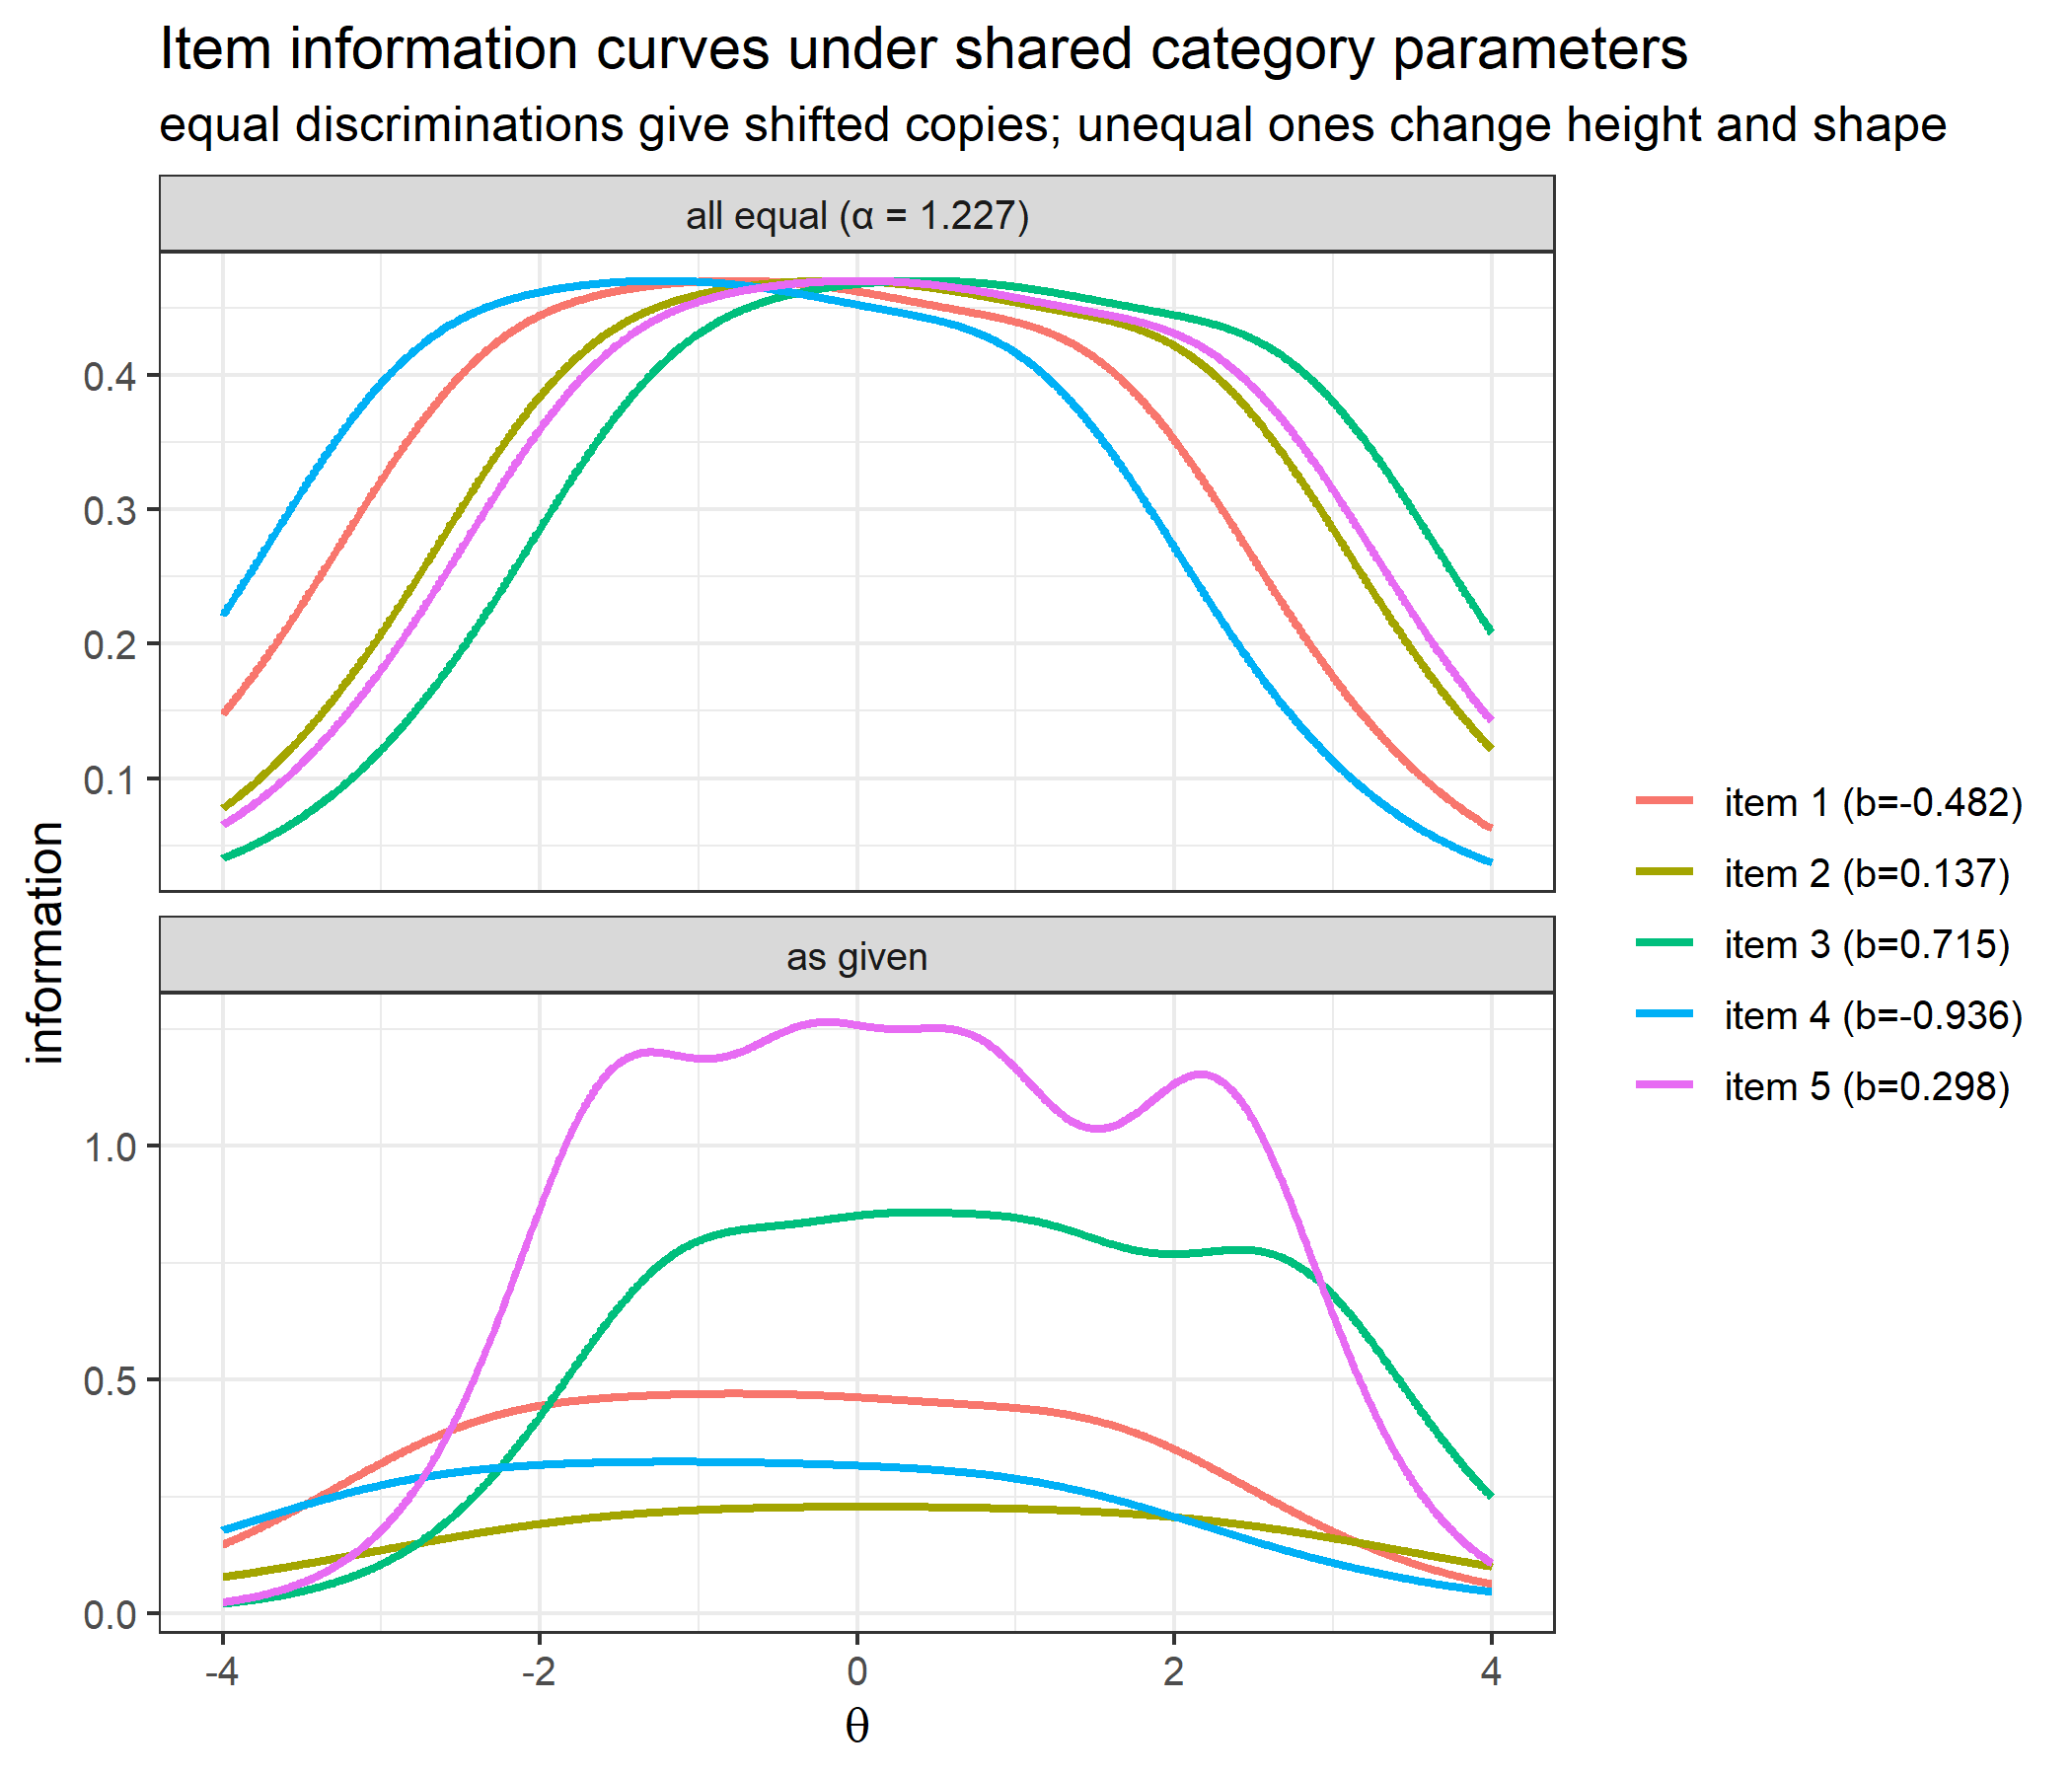
The theory section showed that, within a block, an item's information depends on $\theta$ only through $\theta - b_j$ and on $\alpha_j$. The copy of the bank with equal discriminations isolates the first part. If the claim holds, each item's curve is item 1's curve shifted by $b_j - b_1$:
```{r info_shift}
info_item <- function(b, j, th) sapply(th, function(t) compute_ii_ggrm(t, b[j, , drop = FALSE])$Ii)

shift_check <- sapply(2:5, function(j)
  max(abs(info_item(bank_equal_alpha, j, info_grid) -
          info_item(bank_equal_alpha, 1, info_grid - (bj[j] - bj[1])))))
names(shift_check) <- paste("item", 2:5)
shift_check
```
To rounding error they are. The peaks and heights make the same point:
```{r info_peaks}
peak_summary <- function(b) {
  I <- t(sapply(info_grid, function(th) compute_ii_ggrm(th, b)$Ii))
  data.frame(alphaj = b[, "alphaj"], bj = b[, "bj"],
             peak   = info_grid[apply(I, 2, which.max)],
             max_information = apply(I, 2, max),
             local_maxima = apply(I, 2, function(y) sum(diff(sign(diff(y))) == -2)))
}

peaks_equal <- peak_summary(bank_equal_alpha)
peaks_equal$offset <- peaks_equal$peak - peaks_equal$bj
peaks_equal
```
With equal discriminations every item reaches the same maximum information, at the same offset of about `r round(mean(peaks_equal$offset), 2)` from its own $b_j$ (the offset is not zero because the category parameters are not symmetric around zero, and it is only resolved to the `r diff(info_grid[1:2])` spacing of the grid). The bank then has no strong and weak items, only items aimed at different parts of the scale — and MFI selection among them depends only on where $\theta$ sits relative to the $b_j$. On this grid it is exactly a nearest-neighbour rule on $b_j$ plus the offset:
```{r info_nearest_neighbour}
mfi_equal <- sapply(info_grid, function(th) compute_next_item_ggrm(th, bank_equal_alpha)$item)
nearest   <- sapply(info_grid, function(th) which.min(abs(th - mean(peaks_equal$offset) - bj)))
c(agreements = sum(mfi_equal == nearest), grid_points = length(info_grid))
```
With the discriminations as given, the picture changes:
```{r info_peaks_given}
peaks_given <- peak_summary(bank)
peaks_given$offset <- peaks_given$peak - peaks_given$bj
peaks_given$max_over_alpha2 <- peaks_given$max_information / peaks_given$alphaj^2
peaks_given
```
- The maximum information now ranges from `r round(min(peaks_given$max_information), 3)` (item `r which.min(peaks_given$max_information)`, $\alpha_j =$ `r peaks_given$alphaj[which.min(peaks_given$max_information)]`) to `r round(max(peaks_given$max_information), 3)` (item `r which.max(peaks_given$max_information)`, $\alpha_j =$ `r peaks_given$alphaj[which.max(peaks_given$max_information)]`). Divided by $\alpha_j^2$ the heights fall in the narrow band `r round(min(peaks_given$max_over_alpha2), 3)` to `r round(max(peaks_given$max_over_alpha2), 3)`: the height grows roughly, not exactly, with $\alpha_j^2$.
- The offset of the peak from $b_j$ is no longer constant: `r paste(round(peaks_given$offset, 2), collapse = ", ")`. The discrimination changes the shape of the curve, not just its height.
- The steepest items have more than one local maximum: item `r which.max(peaks_given$alphaj)`, with the largest $\alpha_j$, has `r peaks_given$local_maxima[which.max(peaks_given$alphaj)]`, one per threshold. A large $\alpha_j$ makes each logistic step narrow compared with the gaps between thresholds, and the information separates into one bump per threshold.
```{r info_shape_plot,dev='png'}
info_long <- function(b, label) {
  I <- t(sapply(info_grid, function(th) compute_ii_ggrm(th, b)$Ii))
  d <- data.frame(theta = info_grid, I)
  names(d)[-1] <- paste0("item ", 1:5, " (b=", bj, ")")
  out <- reshape2::melt(d, id.vars = "theta", variable.name = "item", value.name = "information")
  out$discriminations <- label
  out
}

info_both <- rbind(info_long(bank_equal_alpha, "all equal (α = 1.227)"),
                   info_long(bank,             "as given"))

ggplot(info_both, aes(x = theta, y = information, color = item)) +
  geom_line(linewidth = 0.9) +
  facet_wrap(~ discriminations, ncol = 1, scales = "free_y") +
  labs(title = "Item information curves under shared category parameters",
       subtitle = "equal discriminations give shifted copies; unequal ones change height and shape",
       x = expression(theta), y = "information", color = NULL) +
  theme_bw(base_size = 12)
```
---
## Worked example: identifiability and the ordering of the category parameters
### Adding a constant changes nothing
Adding the same constant to every $b_j$ and every $c_k$ ($t = 0.75$ below), or moving to `mirt`'s convention of $b_1 = 0$ ($t = -b_1$), leaves every threshold, and therefore every probability, where it was:
```{r identifiability}
bank_shifted <- bank
bank_shifted[, 2:6] <- bank[, 2:6] + 0.75

bank_mirt_convention <- bank
bank_mirt_convention[, 2:6] <- bank[, 2:6] - bank[1, "bj"]
bank_mirt_convention
max_pi_difference <- function(b1, b2) max(sapply(seq(-4, 4, by = 0.25), function(th) {
  p1 <- compute_pi_ggrm(th, b1)
  p2 <- compute_pi_ggrm(th, b2)
  max(sapply(names(p1), function(k) max(abs(p1[[k]] - p2[[k]]))))
}))

c(shifted_by_0.75 = max_pi_difference(bank, bank_shifted),
  mirt_convention = max_pi_difference(bank, bank_mirt_convention))
x <- c(4, 3, 2, 1, 0)
sprintf("%.12f", c(Muraki  = compute_eap_ggrm(bank, x),
                   shifted = compute_eap_ggrm(bank_shifted, x),
                   mirt    = compute_eap_ggrm(bank_mirt_convention, x)))
```
The differences are floating-point rounding in $b_j - c_k$, never more than `r format(signif(max(max_pi_difference(bank, bank_shifted), max_pi_difference(bank, bank_mirt_convention)), 2))` across all four matrices, and the EAP estimates agree to twelve decimals. The practical consequence: parameters from two calibrations can look very different and still describe the same items. Before comparing $b_j$ or $c_k$ across sources, put them on the same convention — for example centre the $c_k$ of each block at zero, as this bank already is.
### The category parameters must be strictly decreasing
Neither `compute_pi_ggrm()` nor `catR::Pi()` checks the order of the category parameters. Two equal category parameters make two cumulative curves coincide, and the category between them gets probability zero:
```{r ties}
bank_tied <- bank
bank_tied[, "c2"] <- bank[, "c3"]   # c2 = c3
round(compute_pi_ggrm(theta = 0, bank_tied)$Pi, 6)
c(mine = compute_eap_ggrm(bank_tied, c(2, 2, 2, 2, 2)),
  catR = catR::eapEst(bank_tied, c(2, 2, 2, 2, 2), model = "MGRM"))
```
Category 2 is impossible for every item, so a pattern that uses it has likelihood zero everywhere; both integrals are zero and the EAP is `0/0`, which is `NaN` in both implementations. An increasing pair is worse, because nothing fails visibly:
```{r crossed}
bank_crossed <- bank
bank_crossed[, c("c2", "c3")] <- bank[, c("c3", "c2")]   # c2 < c3
P_crossed <- compute_pi_ggrm(theta = 0, bank_crossed)$Pi
round(P_crossed, 6)
rowSums(P_crossed)
```
The cumulative curves cross, category 2 gets a negative "probability", and the rows still sum to 1 because the differences telescope, so a check of the row sums would not catch it. The order has to be checked when the bank is built:
```{r order_check}
check_order <- function(b) all(apply(b[, -(1:2), drop = FALSE], 1,
                                     function(ck) all(diff(ck[!is.na(ck)]) < 0)))
c(bank = check_order(bank), two_blocks = check_order(bank_two_blocks),
  tied = check_order(bank_tied), crossed = check_order(bank_crossed))
```
---
## Worked example: converting a `mirt` graded rating scale fit
The documentation of `compute_pi_ggrm()` gives a recipe for turning a `mirt` model fitted with `itemtype = "grsm"` into a bank. `mirt` writes the cumulative curve as
$$P^*_{jk} = \Psi\big(a_{j}(\theta + c_j + b_k)\big)$$
— note that the letters swap roles: `mirt`'s item parameter is `c` and its category parameters are `b1` to `bm`. Matching that with $\Psi\big(D\alpha_j(\theta - b_j + c_k)\big)$ at $D = 1$ gives the conversion, with `mirt`'s parameters on the right-hand sides:
$$\alpha_j = a_j, \qquad b_j = -c_j, \qquad c_k = b_k \qquad (D = 1).$$
To check the recipe, 1000 examinees are simulated from the bank, the model is fitted with `mirt`, and the converted bank is compared with `mirt`'s own trace lines.
```{r mirt_fit}
set.seed(123)
n_examinees <- 1000
theta_sim <- rnorm(n_examinees)
responses_sim <- t(sapply(theta_sim, function(th) {
  p <- compute_pi_ggrm(th, bank)$Pi
  apply(p, 1, function(pr) sample(0:4, size = 1, prob = pr))
}))
colnames(responses_sim) <- paste0("item", 1:5)

fit <- mirt::mirt(as.data.frame(responses_sim), 1, itemtype = "grsm", verbose = FALSE)
pars <- mirt::coef(fit, simplify = TRUE)$items
round(pars, 3)
mirt::coef(fit, simplify = TRUE)[c("means", "cov")]
```
`mirt` has fixed $c_j = 0$ for the first item — its identifiability convention — and in this fit the latent distribution has mean 0 and variance 1, the same standard normal the EAP functions use as their default prior. The conversion:
```{r mirt_convert}
bank_mirt <- cbind(pars[, "a1"], -pars[, "c"], pars[, grep("^b[0-9]", colnames(pars))])
colnames(bank_mirt) <- colnames(bank)
round(bank_mirt, 3)
trace_grid <- seq(-4, 4, by = 0.1)
trace_difference <- sapply(1:5, function(j) {
  mirt_trace <- mirt::probtrace(mirt::extract.item(fit, j), matrix(trace_grid))
  mine <- t(sapply(trace_grid, function(th) compute_pi_ggrm(th, bank_mirt[j, , drop = FALSE])$Pi[1, ]))
  max(abs(mirt_trace - mine))
})
names(trace_difference) <- paste("item", 1:5)
trace_difference
```
The converted bank reproduces `mirt`'s trace lines for every item to within `r format(signif(max(trace_difference), 2))` over the whole grid, so the recipe is right. The converted bank uses `mirt`'s convention, $b_1 = 0$; re-centring its category parameters at zero, as in the generating bank (the shift by $t = -\bar c$ from the theory section, $b_j - \bar c$ and $c_k - \bar c$), makes the estimates directly comparable with the values they were simulated from:
```{r mirt_recovery}
bank_mirt_centred <- bank_mirt
bank_mirt_centred[, 2:6] <- bank_mirt[, 2:6] - mean(bank_mirt[1, 3:6])

recovery <- data.frame(alphaj_true = bank[, "alphaj"], alphaj_mirt = bank_mirt_centred[, "alphaj"],
                       bj_true     = bank[, "bj"],     bj_mirt     = bank_mirt_centred[, "bj"])
round(recovery, 3)
round(rbind(true = bank[1, 3:6], mirt = bank_mirt_centred[1, 3:6]), 3)
c(max_difference = max(abs(bank_mirt_centred - bank)))
```
On a common convention the estimates are close to the generating values, the largest difference being `r round(max(abs(bank_mirt_centred - bank)), 3)` — the sampling error of a calibration on `r n_examinees` simulated examinees. Without the re-centring the locations would appear to disagree by the arbitrary constant that the two conventions differ by.
---
## Worked example: a short adaptive test
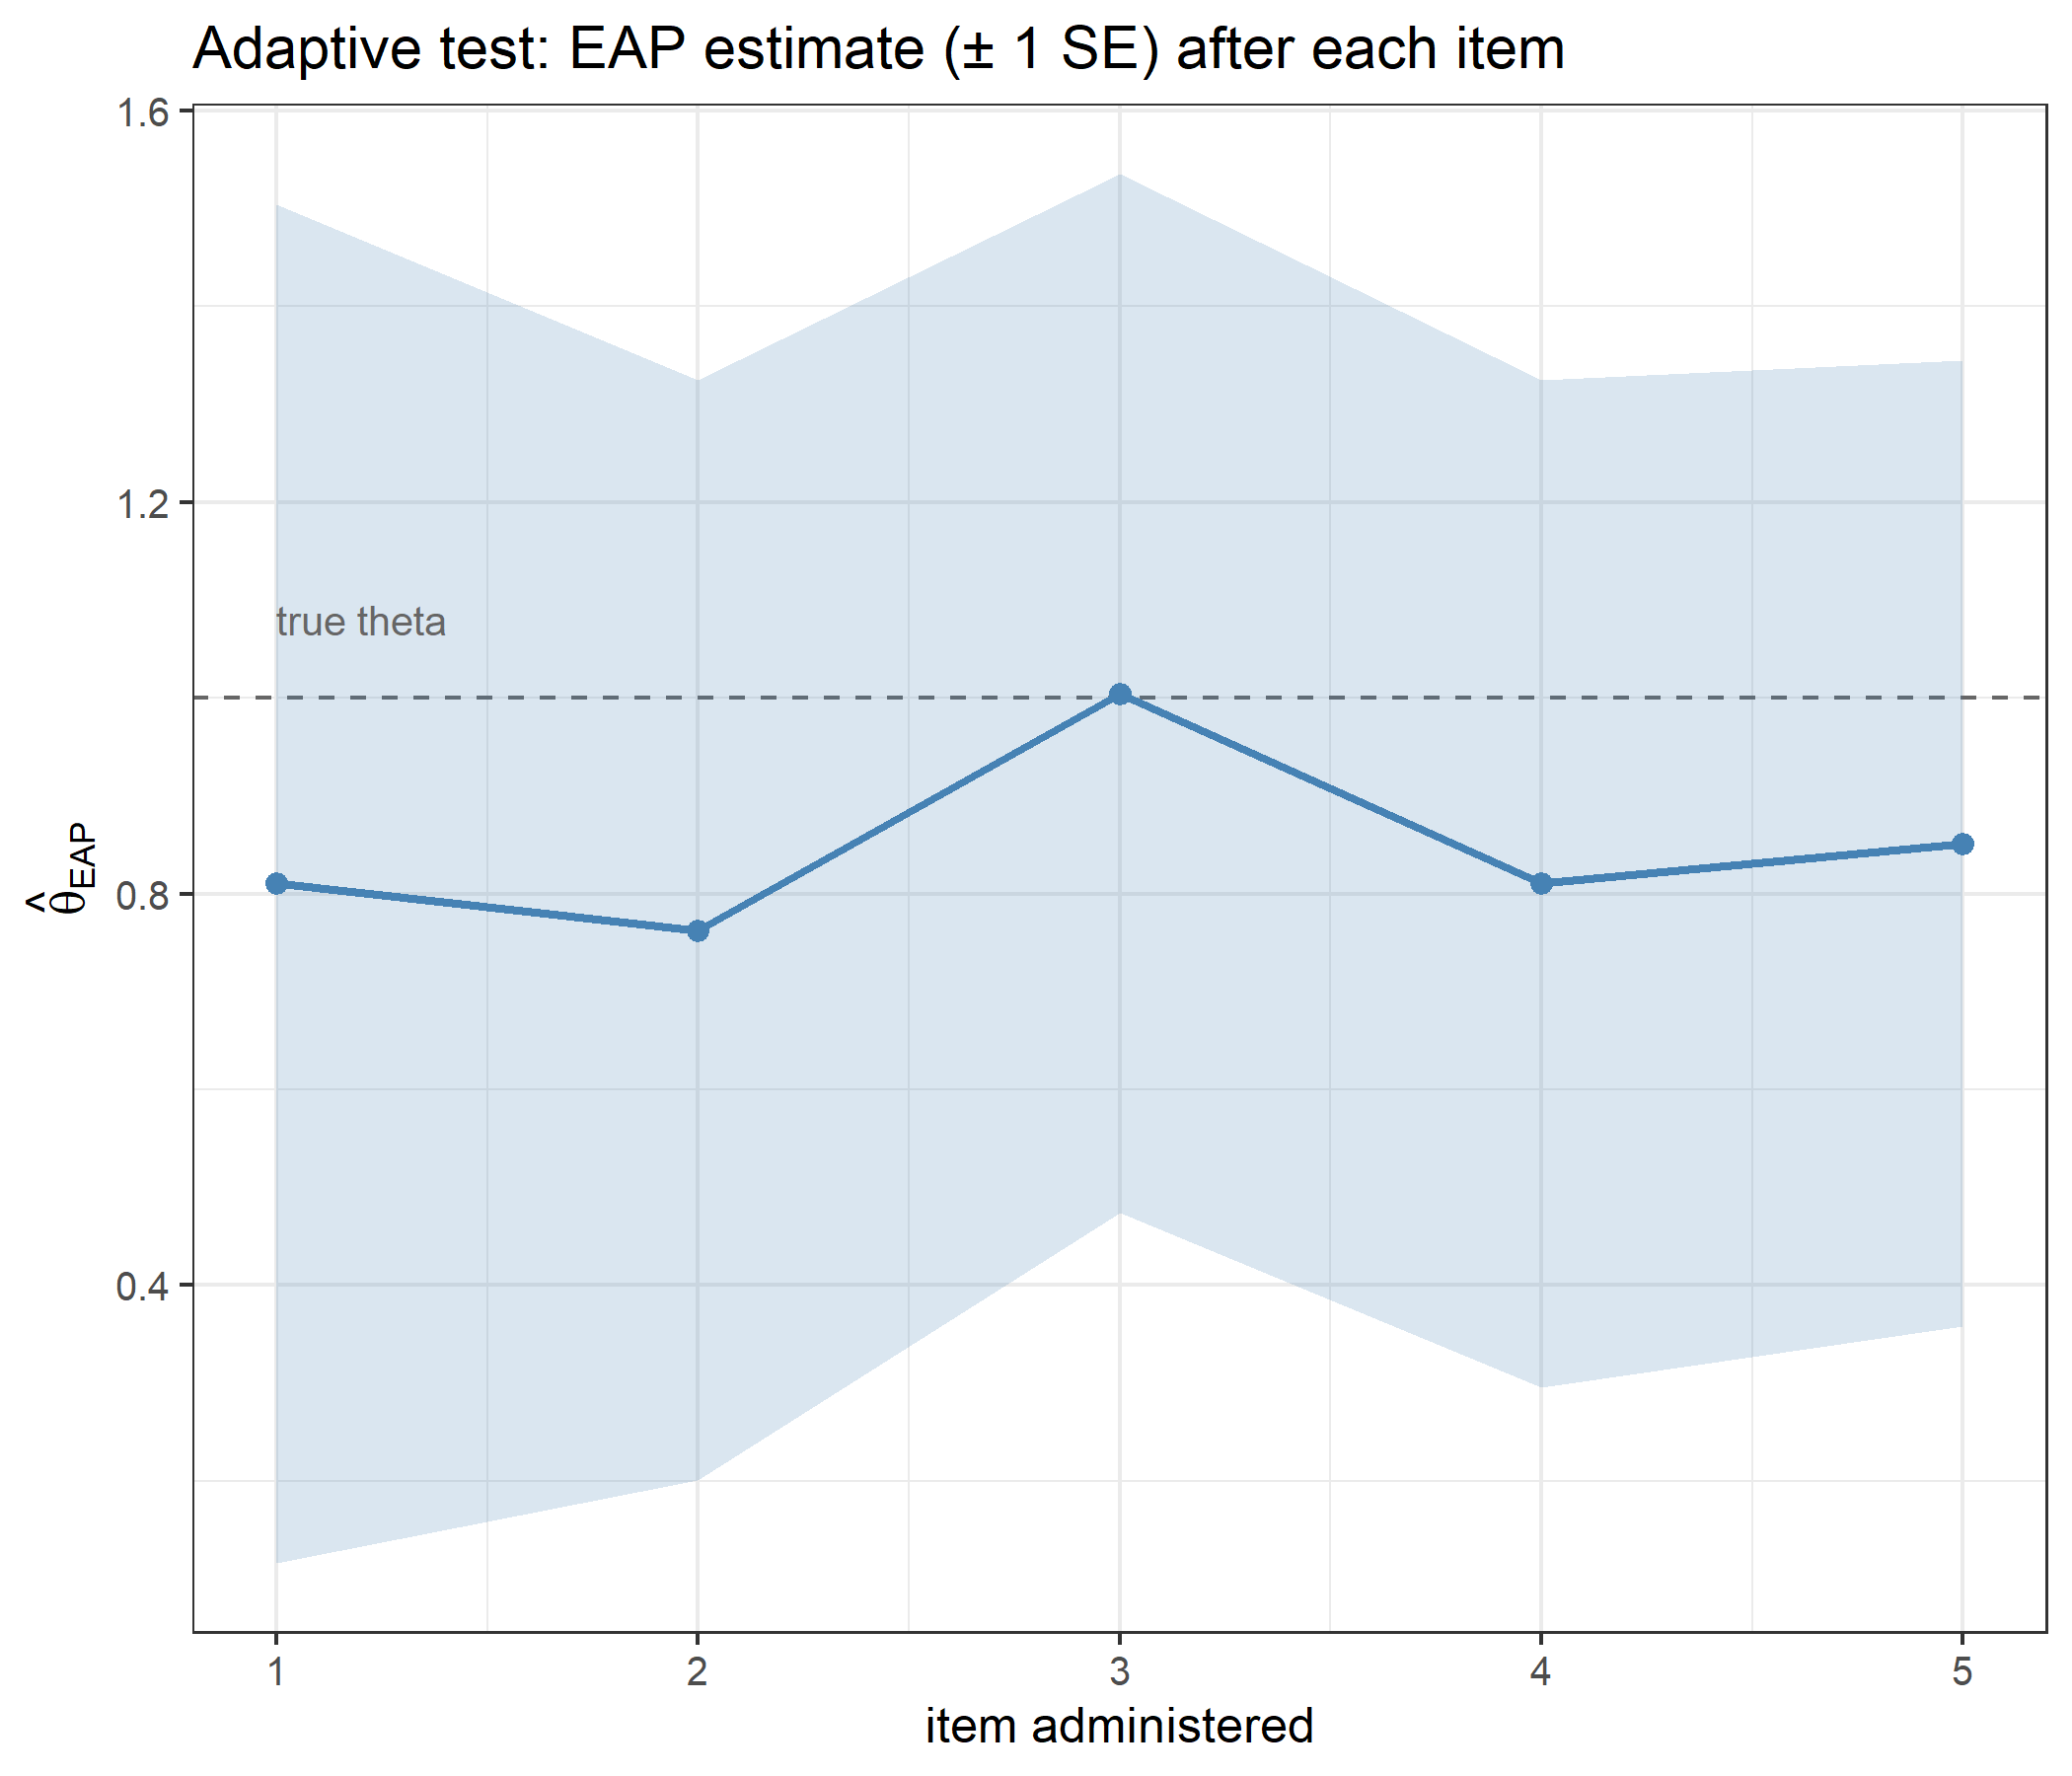
Everything above assembles into an adaptive loop. At each step, pick the most informative unadministered item at the current estimate, collect a response, rescore, repeat.
```{r adaptive}
set.seed(1)
true_theta <- 1.0

# simulate a response to item j from an examinee at true_theta
simulate_response <- function(j, theta) {
  p <- compute_pi_ggrm(theta, bank[j, , drop = FALSE])$Pi[1, ]
  p <- p[!is.na(p)]
  sample(0:(length(p) - 1), size = 1, prob = p)
}

theta <- 0
administered <- integer(0)
responses <- integer(0)
trace <- data.frame()

for (step in 1:5) {
  sel <- compute_next_item_ggrm(theta, bank, out = administered)
  administered <- c(administered, sel$item)
  responses <- c(responses, simulate_response(sel$item, true_theta))

  sub_bank <- bank[administered, , drop = FALSE]
  theta <- compute_eap_ggrm(sub_bank, responses)
  se <- compute_eap_se_ggrm(theta, sub_bank, responses)

  trace <- rbind(trace, data.frame(step = step, item = sel$item,
                                   alphaj = bank[sel$item, "alphaj"],
                                   bj = bank[sel$item, "bj"],
                                   information = sel$info,
                                   response = tail(responses, 1),
                                   theta_EAP = theta, SE = se))
}
trace
```
```{r adaptive_plot,dev='png'}
ggplot(trace, aes(x = step, y = theta_EAP)) +
  geom_hline(yintercept = true_theta, linetype = "dashed", color = "grey40") +
  geom_ribbon(aes(ymin = theta_EAP - SE, ymax = theta_EAP + SE),
              alpha = 0.2, fill = "steelblue") +
  geom_line(color = "steelblue", linewidth = 1) +
  geom_point(size = 2, color = "steelblue") +
  annotate("text", x = 1, y = true_theta + 0.08, hjust = 0,
           label = "true theta", color = "grey40", size = 3.5) +
  scale_x_continuous(breaks = trace$step) +
  labs(title = "Adaptive test: EAP estimate (± 1 SE) after each item",
       x = "item administered", y = expression(hat(theta)[EAP])) +
  theme_bw(base_size = 12)
```
The loop opens with item `r trace$item[1]`, the most discriminating item in the bank, and then takes the items in the order `r paste(trace$item, collapse = ", ")`, which is also the order of decreasing discrimination (`r paste(trace$alphaj, collapse = ", ")`). The standard error falls at every step, from `r round(trace$SE[1], 3)` after one item to `r round(trace$SE[5], 3)` after five, and the final estimate is `r round(trace$theta_EAP[5], 3)` for a true ability of `r true_theta`. Unlike a rating scale bank, where every item is equally good and only the targeting differs, the discrimination dominates the choice here.
### Exposure control
Pure MFI is deterministic: every examinee starting at $\theta = 0$ receives the same first item. Across the whole ability range the steepest item is chosen most of the time:
```{r mfi_share}
mfi_given <- sapply(info_grid, function(th) compute_next_item_ggrm(th, bank)$item)
round(table(mfi_given) / length(mfi_given), 3)
```
Item `r names(which.max(table(mfi_given)))` is the MFI choice at `r round(100 * max(table(mfi_given)) / length(mfi_given), 1)`% of the grid points between $-4$ and $4$`r if (any(!(1:5 %in% mfi_given))) paste0(", and item ", paste(setdiff(1:5, mfi_given), collapse = " and "), " is never the first choice anywhere on the grid") else ""`. The `randomesque` argument draws at random from the $k$ best instead:
```{r randomesque}
set.seed(42)
table(replicate(2000, compute_next_item_ggrm(theta = 0, bank, randomesque = 1)$item))
table(replicate(2000, compute_next_item_ggrm(theta = 0, bank, randomesque = 3)$item))
```
With `randomesque = 1` the same item is chosen 2000 times out of 2000; with `randomesque = 3` the load is spread over three items. Because the items here differ in how informative they can be, the cost is much larger than in a bank with equal discriminations:
```{r randomesque_cost}
randomesque_cost <- function(b) {
  info_at_0 <- compute_ii_ggrm(theta = 0, b)$Ii
  top3 <- sort(info_at_0, decreasing = TRUE)[1:3]
  c(best_item = max(info_at_0), mean_of_top_3 = mean(top3),
    proportion_of_best = mean(top3) / max(info_at_0))
}
rbind(as_given = randomesque_cost(bank), equal_alpha = randomesque_cost(bank_equal_alpha))
```
Drawing from the top three keeps `r round(100 * randomesque_cost(bank)["proportion_of_best"])`% of the information of the best item with the discriminations as given, against `r round(100 * randomesque_cost(bank_equal_alpha)["proportion_of_best"])`% when they are equal. That is the usual trade-off between measurement efficiency and item security, and in an MGRM bank with a wide spread of discriminations it is a real trade.
---
## Worked example: the numerical settings
The EAP integrals are approximations, and four arguments control them. None of these is a free choice to make casually.
```{r settings}
x <- c(4, 4, 4, 4, 4)   # the hardest case for numerical integration

settings <- rbind(
  data.frame(setting = "quadrature points", value = c(11, 33, 101, 501),
             theta = sapply(c(11, 33, 101, 501),
                            function(n) compute_eap_ggrm(bank, x, nqp = n))),
  data.frame(setting = "integration bound", value = c(3, 4, 6),
             theta = sapply(c(3, 4, 6),
                            function(b) compute_eap_ggrm(bank, x, lower = -b, upper = b))),
  data.frame(setting = "prior SD", value = c(1, 2),
             theta = sapply(c(1, 2),
                            function(s) compute_eap_ggrm(bank, x, priorPar = c(0, s)))),
  data.frame(setting = "metric constant D", value = c(1, 1.702),
             theta = sapply(c(1, 1.702),
                            function(d) compute_eap_ggrm(bank, x, D = d)))
)
settings
```
```{r settings_values, include=FALSE}
s_nqp <- settings$theta[settings$setting == "quadrature points"]
s_bound <- settings$theta[settings$setting == "integration bound"]
s_prior <- settings$theta[settings$setting == "prior SD"]
s_D <- settings$theta[settings$setting == "metric constant D"]
```
Three different kinds of effect are visible here, and they should not be confused with one another:
- **Quadrature points** are pure approximation error. Moving from 11 to 33 points changes the estimate by `r format(signif(abs(s_nqp[2] - s_nqp[1]), 2))`, from 33 to 101 by `r format(signif(abs(s_nqp[3] - s_nqp[2]), 2))`, and from 101 to 501 by `r format(signif(abs(s_nqp[4] - s_nqp[3]), 2))`. The default of 33 is a reasonable accuracy/speed compromise and matches `catR`.
- **Integration bounds** are also approximation error, but of a more dangerous kind. Truncating at $\pm 3$ moves the estimate by `r round(abs(s_bound[2] - s_bound[1]), 3)`, because for an all-highest pattern the posterior still has real mass beyond $\theta = 3$ and cutting it off silently biases the estimate downward. Widening from $\pm 4$ to $\pm 6$ moves it by `r round(abs(s_bound[3] - s_bound[2]), 3)`. Bounds must be wide enough for the *most extreme pattern the bank can produce*, not for a typical one.
- **The prior SD and the metric constant are not approximation error at all** — they are different models. Doubling the prior SD to 2 weakens the shrinkage and moves the estimate from `r round(s_prior[1], 2)` to `r round(s_prior[2], 2)`; setting $D = 1.702$ multiplies every discrimination by 1.702 and moves it to `r round(s_D[2], 2)`. Both belong in the model specification and must match whatever was used to calibrate the item parameters — for a `mirt` calibration, $D = 1$.
---
## Worked example: numerical precision of the category probabilities
A category probability is a difference of two cumulative probabilities. Far above an item's thresholds both are close to 1, and their difference loses precision. The documentation of `compute_pi_ggrm()` warns about this, and it is easy to see on the steepest item: category 0 of item 5 is $1 - P^*_{51}$, which can also be computed accurately as the upper tail of the logistic distribution.
```{r precision}
theta_far <- c(4, 8, 12, 16, 20)
beta_51 <- bank[5, "bj"] - bank[5, "c1"]

precision <- data.frame(
  theta    = theta_far,
  computed = sapply(theta_far, function(t) compute_pi_ggrm(t, bank[5, , drop = FALSE])$Pi[1, "cat0"]),
  catR     = sapply(theta_far, function(t) catR::Pi(t, bank[5, , drop = FALSE], model = "MGRM")$Pi[1, "cat0"]),
  accurate = plogis(bank[5, "alphaj"] * (theta_far - beta_51), lower.tail = FALSE))
precision$relative_error <- abs(precision$computed - precision$accurate) / precision$accurate
precision
```
At $\theta = 4$, the upper integration bound, the relative error is `r format(signif(precision$relative_error[1], 2))`. It grows as the true probability shrinks towards the size of the rounding error in numbers close to 1: at $\theta = 12$ it is `r format(signif(precision$relative_error[3], 2))`, and further out the computed value is `r format(precision$computed[4])` at $\theta = 16$ and `r format(precision$computed[5])` at $\theta = 20$, where the accurate values are `r format(signif(precision$accurate[4], 2))` and `r format(signif(precision$accurate[5], 2))`. `catR` computes these probabilities the same way and returns the same values. The problem only arises for a response far below what $\theta$ predicts on a steep item, at abilities far outside the default integration range of this bank, so it has no visible effect on any EAP result in this vignette.
---
# Conclusion
All eight functions used here reproduce their `catR` counterparts: the normal density, the trapezoidal integrator, the MGRM category probabilities with all three derivatives (for items padded with `NA` as well), the item information with both derivatives, MFI item selection with and without excluded items, the likelihood (rebuilt from `catR`'s probabilities, since `catR` does not export one), and the two integrals that define EAP scoring, at both metric constants and for extreme patterns as well as ordinary ones. The only documented differences, both in the handling of exactly tied items in selection, show up only when a tie is built in on purpose.
Written out, the model's character is easy to see. The MGRM is the graded response model with its thresholds split into an item location and category parameters shared across a block — a restriction, which `compute_pi_ggrm()` makes literal by forming $b_j - c_k$ and then running the GRM code unchanged. Sharing the category parameters makes the information curves of equally discriminating items shifted copies of one another, but because the model keeps the item discrimination, a real bank has strong and weak items, the most discriminating item dominates adaptive selection, and exposure control has a visible cost. The split between locations and category parameters is not identified without a constraint, so parameters from different sources must be put on one convention before they are compared, and the category parameters must be strictly decreasing, which nothing in the code checks. Finally, a `mirt` graded rating scale fit converts into this layout with a three-column recipe that reproduces `mirt`'s trace lines to machine precision.
---
# References
- Bock, R. D., & Mislevy, R. J. (1982). Adaptive EAP estimation of ability in a microcomputer environment. *Applied Psychological Measurement, 6*(4), 431–444.
- Magis, D., & Barrada, J. R. (2017). Computerized adaptive testing with R: Recent updates of the package catR. *Journal of Statistical Software, Code Snippets, 76*(1), 1–19. https://doi.org/10.18637/jss.v076.c01
- Magis, D., & Raîche, G. (2012). Random generation of response patterns under computerized adaptive testing with the R package catR. *Journal of Statistical Software, 48*(8), 1–31. https://doi.org/10.18637/jss.v048.i08
- Muraki, E. (1990). Fitting a polytomous item response model to Likert-type data. *Applied Psychological Measurement, 14*(1), 59–71.
- Samejima, F. (1969). Estimation of latent ability using a response pattern of graded scores. *Psychometrika Monograph Supplement, 34*(4, Pt. 2), No. 17.
---
*Rendered with R `r getRversion()` · validated against catR `r as.character(packageVersion("catR"))`*